

Techandtips123
6.7k Publications

Techandtips123
 Compte Square Vérifié+
Signaler
Bloquer l’utilisateur
✅ PROMO - @iamdkbc ✅ Data Driven Crypto On-Chain Research & Analysis. X @Techandtips123

2025 Blockchain 100 — Independent Researcher

Traders League Badge Beginner

Top Voices
Trade occasionnellement
5.7 an(s)
21 Suivis
60.6K+ Abonnés
74.4K+ J’aime
4 Badges
Publications
Tous
Citations
Vidéos
Direct
PINNED
Article
Deep Dive : The Nvidia Vera Rubin NarrativeThe global technology sector is undergoing a massive infrastructure upgrade cycle. Artificial intelligence models require unprecedented computing power to function. Hardware designers must constantly innovate to meet these demands. The newest inflection point in this cycle is the Nvidia Vera Rubin platform. This architecture is the direct successor to the Blackwell generation. Vera Rubin represents a fundamental redesign of how modern data centers process information.
The entire platform centers around a newly engineered processing unit. This central component is the Rubin graphics processing unit. The Rubin chip uses a new generation of high bandwidth memory known as HBM4. This advanced memory architecture delivers extraordinary speeds. A single Rubin processor provides up to 288 gigabytes of HBM4 memory. The data transfer bandwidth reaches an astonishing 22 terabytes per second. This massive increase in memory speed is critical for running complex artificial intelligence tasks.
The Rubin processor requires a vast supporting cast of specialized hardware to function. Leading the charge is the Vera central processing unit, which handles complex data orchestration and host system management. Packed with 88 distinct custom Olympus ARM cores and 176 threads of spatial multithreading, Vera’s sole job is to keep the Rubin processors constantly fed with data so they never sit idle.
To connect these powerful chips without creating a massive communication bottleneck, the architecture uses the NVLink 6 switch. This interconnect provides direct physical pathways, delivering an incredible 3.6 terabytes per second of bandwidth per individual processor.
This blazing-fast connection allows dozens of separate chips to function seamlessly as a single computing brain. Nvidia packages these components into massive flagship rack systems known as the NVL72, where a single rack contains 72 Rubin processors, 36 Vera processors, and a total memory capacity hitting 20.7 terabytes.
Scaling beyond a single rack introduces severe physical bottlenecks. Connecting entire server farms requires advanced external networking hardware, and scaling up to 576 processors requires new systems like the Kyber NVL1152. Nvidia addresses these network limits with the Spectrum-X Ethernet system and co-packaged optics.
These components provide the massive scale-out fabric necessary for artificial intelligence factories. Because traditional copper cables degrade data signals rapidly over short distances at these extreme speeds, the architecture must transition to silicon photonics, using optical lasers to transmit data while reducing power consumption and lowering network latency.
The deployment of the Vera Rubin platform forces a massive shift across the entire technology sector, requiring complete supply chain mobilization. The rollout demands novel custom silicon designs, entirely new optical connective tissue, and unprecedented levels of physical cloud compute capacity, meaning investors cannot capture this shift by simply buying a single hardware stock.
This deployment requires a structured approach to the infrastructure stack. Positioning for this catalyst requires understanding exactly how capital flows from the end users down to the base component manufacturers.
❍ Core Company Profiles: The Vera Rubin Connection
>> NBIS (Nebius) Nebius serves as the direct physical deployment layer for the Vera Rubin architecture. The company buys the finished NVL72 racks and HBM4 components to build supercomputing clusters. Investors must care about Nebius because it translates raw Nvidia hardware into rentable cloud capacity. They act as the immediate end customer for the physical components. Their explosive revenue growth serves as a direct proxy for early stage Vera Rubin market demand. If Vera Rubin is a massive commercial success, Nebius captures the immediate rental revenue.
>> CRWV (CoreWeave) CoreWeave acts as an aggressive aggregator of Vera Rubin platforms. The firm secures massive debt to purchase the newest Rubin processors and networking switches. CoreWeave matters to this narrative because it pushes the architectural shift forward much faster than traditional public clouds. They convert the raw silicon innovations of Vera Rubin into recurring rental agreements for artificial intelligence laboratories. The company is actively building new global data centers specifically designed to house the extreme power density of these massive new server racks.
>> AVGO (Broadcom) Broadcom is the fundamental silicon bedrock supporting the Vera Rubin ecosystem. The company designs the custom accelerators and the Tomahawk networking switches required to bind tens of thousands of processors together. Investors must focus on Broadcom because massive Vera Rubin systems simply cannot function without these high speed networking chips. They provide a highly stable and mature way to profit from the physical transition. Broadcom collects immense revenue regardless of which cloud provider ultimately wins the compute war.
>> COHR (Coherent) Coherent provides the critical optical connective tissue required for Vera Rubin data speeds. The Rubin architecture moves data so fast that traditional copper cables fail over short distances. Coherent manufactures the necessary indium phosphide lasers and co-packaged optics. Investors should focus on Coherent because their components are an absolute physical requirement to build massive Vera Rubin server farms. Nvidia directly invested two billion dollars into Coherent specifically to secure this exact supply chain.
>> LITE (Lumentum) Lumentum supplies the high power continuous wave lasers essential for Vera Rubin scale up networking. The company physically enables the massive optical connections between individual processors. Lumentum is crucial to the catalyst because they hold the specific manufacturing capacity required to overcome severe optical supply bottlenecks. Nvidia also deployed a matching two billion dollar investment into Lumentum to guarantee access to these critical laser components for future infrastructure rollouts.
I. Positioning in the 3-Layer Stack
The deployment of the $NVDA Vera Rubin architecture requires a massive and highly complex supply chain. The five profiled companies provide structured exposure across three very distinct layers of a singular value chain. Evaluating these stocks requires a deep understanding of exactly where they sit within this hierarchy. Risk profiles behave very differently depending on the specific layer occupied. Profit margins face completely different structural pressures across each vertical level. Stack position sets the foundational frame that every other financial metric must be read through.
Layer 1 represents the pure Silicon foundation. Broadcom dominates this space. Broadcom designs custom artificial intelligence accelerators for hyperscale clients like Google and Meta. These custom chips serve as highly efficient alternatives to standard off the shelf graphics processing units. Broadcom builds the essential networking switches that physically connect these diverse processors. The company straddles both compute generation and physical networking design. This specific position is highly insulated from downstream volatility. Broadcom collects immense revenue regardless of which software application succeeds in the consumer market.
Layer 2 represents the Interconnect and Photonics segment. Coherent and Lumentum jointly occupy this critical space. These companies manufacture the optical transceivers and laser components that allow massive processor clusters to function as a single synchronized machine. They do not build the core computational processing chips. They do not operate the physical cloud data centers. They simply manufacture and sell the connective tissue. This layer currently faces a severe physical supply constraint regarding indium phosphide components. Indium phosphide is the base material required to manufacture the specific lasers used in high speed data transfer. This physical bottleneck is the direct cause of sharp recent margin expansion for both companies. The fundamental physics of data transfer at Vera Rubin speeds mandate specialized optical solutions.
Layer 3 represents the Compute and Cloud segment. Nebius and CoreWeave operate exclusively at this top level. These specialized neoclouds purchase the hardware produced by the lower foundational layers. They assemble the diverse components into finished compute capacity. They then rent this capacity out to enterprise clients. This layer sits closest to the actual algorithmic model training work. It is the most capital intensive tier of the entire stack. It is the least mature regarding pure operating profitability. Nebius and CoreWeave act as the primary end customers for the products designed by Broadcom, Coherent, and Lumentum. Positioning at this layer carries the absolute highest operational risk.
The structural reality of this three layer stack dictates overall investment strategy. The silicon and interconnect layers collect their payment upfront during the initial infrastructure buildout phase. They bear very little long term risk regarding the ultimate commercial viability of the end user applications. The compute layer pays heavily for physical capacity today in exchange for projected rental margins tomorrow.
II. Top-Line Growth Momentum
Revenue growth metrics provide a highly clear picture of current momentum within the supply chain. Growth rates must be analyzed relative to the base size of the specific company being evaluated. Raw percentages can obscure the actual scale of capital flowing through a business.
The tabulated data reveals a stark inverse relationship between the base size of the company and its headline growth rate. The newest and smallest infrastructure providers post the most explosive percentage numbers. Nebius achieved a massive 684 percent year over year revenue increase in its most recent quarter. CoreWeave delivered a staggering 112 percent growth on a much larger multibillion dollar base. These figures highlight the massive influx of capital pouring into Layer 3 of the infrastructure stack. Technology startups are aggressively booking compute capacity for future use. This drives immediate top line expansion for the specialized neocloud operators.
Broadcom presents a vastly more complex growth narrative. The company reported a 48 percent total year over year growth rate on its blended corporate book. This blended figure vastly understates the actual momentum of its specific artificial intelligence operations. The dedicated artificial intelligence segment within Broadcom grew at an incredible 143 percent year over year. This isolated segment growth perfectly matches the explosive acceleration seen in Layer 3 providers like CoreWeave. The market must parse these segments to understand the real hardware demand curve.
The photonics providers in Layer 2 show strong but varying momentum profiles. Lumentum reported impressive 90 percent year over year growth in the latest quarter. Coherent posted a more modest 21 percent increase during a similar period. This specific growth is heavily dictated by complex supply chain mechanics and manufacturing capacity constraints. The demand for optical transceivers outstrips the current global manufacturing supply. Their top line growth reflects their physical ability to produce units rather than any lack of end customer demand.
III. Operating Margin Trajectory
Revenue growth indicates general market momentum. Operating margins reveal the actual quality and long term sustainability of that specific growth. The fundamental unit economics behave drastically different depending on precise stack positioning. Fast growth often requires destroying near term profitability to secure future market share.
This specific parameter serves as the clearest statistical illustration of the entire layering thesis. The financial profiles of these individual companies directly reflect their physical operational roles. Broadcom operates with a highly mature and incredibly stable margin of 67 percent. The company incurs massive research and development costs upfront to design new chips. Selling high end networking chips at scale produces immense profit. Broadcom collects massive cash flows immediately upon physical product delivery to the end user.
CoreWeave presents a genuine and severe margin deterioration story. The company saw its adjusted operating margin collapse to a mere one percent. This represents a massive drop from 17 percent in the previous year. This severe contraction ties directly to massive front loaded capital expenditures. CoreWeave borrows tens of billions of dollars to purchase raw hardware and build vast physical data centers. The aggressive depreciation schedules and surging interest expenses drag down current profitability. Corporate management characterizes this current period as the absolute low point of their margin cycle.
Nebius displays highly similar financial dynamics. The company achieved a strong 45 percent adjusted EBITDA within its specific artificial intelligence cloud segment. The broader group operating income remains distinctly negative. Nebius currently navigates an intense hypergrowth capital expenditure phase. Building the physical infrastructure required to house massive new server clusters drains operating capital rapidly.
The Layer 2 photonics companies show real and highly profitable early stage margin inflections. Lumentum expanded its margin by an incredible 2,140 basis points year over year. Coherent maintains a steady climb toward 20.3 percent. This margin expansion is heavily driven by structural supply constraints across the broader tech industry. The global market lacks sufficient indium phosphide fabrication capacity. This deep shortage grants Coherent and Lumentum immense pricing power over their clients. Customers must pay significant premium rates to secure the optical transceivers necessary for their network deployments.
IV. Backlog and Revenue Visibility
Backlog metrics determine exactly how much of a company's future growth narrative is already contractually secured. This contrasts sharply with revenue that remains entirely speculative. High revenue visibility drastically reduces investment risk during turbulent macro market cycles.
CoreWeave and Broadcom provide the most rigorous and highly quantified backlog disclosures among the evaluated group. CoreWeave boasts a staggering 99.4 billion dollar forward revenue backlog. The company provides specific timelines for actual realization. They expect 36 percent fulfillment within two years. They project 75 percent fulfillment within four years. This massive contractual foundation allows CoreWeave to secure its vast debt financing.
Broadcom offers similarly transparent visibility to its investors. The company holds a 73 billion dollar backlog specifically tied to its artificial intelligence segment alone. The total performance obligations across the entire diversified corporate business reach an incredible 164.6 billion dollars. This unmatched forward visibility proves that the hyperscaler infrastructure buildout remains highly durable. The spending plans of major technology firms are completely well funded for the next several years.
Nebius showcases deep visibility despite its significantly smaller current revenue base. The company holds roughly 21.3 billion dollars in formal remaining performance obligations. The total contracted deal value stretches between 46 and 50 billion dollars. This massive value is largely anchored by binding agreements with Microsoft and Meta. These long term contracts extend deep into the year 2031.
A notable transparency gap exists within Layer 2. Coherent and Lumentum discuss their backlog with immense qualitative confidence. Coherent cites record backlog numbers stretching deep into calendar year 2028. Neither company publishes a comprehensive company wide dollar figure for their forward obligations. Investors must treat this total lack of numerical disclosure as a specific transparency gap.
V. Recent Catalysts
Trailing financial metrics only tell a small portion of the corporate story. Recent structural milestones and aggressive corporate actions heavily dictate short term momentum. These events validate long term operational strategies and signal shifts in the broader market landscape.
Two distinct patterns run across all five profiled companies. The first pattern is massive and deliberately directed capital intervention by Nvidia. Nvidia is aggressively taking direct equity stakes at multiple vertical levels of the infrastructure stack simultaneously. The hardware giant acquired a 9.3 percent equity stake in Nebius at the top compute layer. This formalizes a tight operational bond between the chip designer and the physical data center operator.
Simultaneously, Nvidia deployed four billion dollars directly into the middle Layer 2. They injected two billion dollars into Coherent. They injected two billion dollars into Lumentum. These targeted investments were immediately paired with multi year procurement commitments for advanced laser components. This specific behavior clearly outlines a strategy of total supply chain capture. Nvidia uses its massive corporate balance sheet to lock down the critical physical production capacity required for future rollouts.
The second major pattern involves aggressive global operational scaling. CoreWeave executed a major physical expansion into Europe by signing a strategic colocation deal with Conapto. This vital agreement places new compute capacity across two completely renewable powered data campuses in Stockholm. CoreWeave also signed a massive 335 million dollar storage agreement with Backblaze. This deal serves to offload lower tier data management tasks. This frees up premium server capacity for highly lucrative algorithmic training workloads.
Broadcom secured massive long term corporate stability by extending its custom chip partnership with Apple through the year 2031. This single contract firmly locks in roughly 20 percent of Broadcom corporate revenue for years. Lumentum responded directly to the optical supply bottleneck by rapidly acquiring a fifth indium phosphide fabrication facility in North Carolina. These diverse catalysts demonstrate a global supply chain moving rapidly to accommodate unprecedented physical scaling demands.
VI. Valuation Matrix
Valuation accurately contextualizes raw growth. Evaluating overall enterprise value against forward revenue projections provides a critical analytical filter. It determines whether a fundamentally high quality business actually represents a viable investment at its current market trading price.
The comprehensive valuation matrix reveals deep nuances beneath the headline numbers. Nebius and CoreWeave screen as the absolute cheapest assets relative to their sheer top line growth rates. Nebius carries an exceptionally low 0.021 comparative ratio. CoreWeave sits at a highly attractive 0.046 ratio. These metrics contain severe operational caveats.
The incredible 684 percent growth rate posted by Nebius occurs off an incredibly tiny baseline revenue figure. This specific rate of mathematical acceleration will fundamentally never repeat as the base denominator scales upward over time. CoreWeave appears exceptionally cheap on an enterprise value basis until structural debt is fully contextualized. Tens of billions of dollars in highly structured physical facility debt must be added back into the core calculation.
Broadcom appears relatively expensive when evaluating its purely blended corporate growth. The stock commands a massive 1.9 trillion dollar enterprise value. It currently trades at roughly 19 times forward revenue estimates. Applying the blended 48 percent growth rate yields a ratio of 0.40. The valuation becomes far more reasonable when isolated strictly to its artificial intelligence segment. The 143 percent segment growth rate drops the comparative ratio down to a highly attractive 0.13.
The middle optics layer presents a sharply split valuation dynamic. Coherent trades at a relatively modest 7.5 times forward revenue. Lumentum trades at a significantly richer 18.3 times forward revenue. This distinct premium valuation for Lumentum reflects the broader market rewarding its sharper near term margin expansion.
VII. Customer Concentration
Customer concentration represents a highly critical risk parameter. Heavy reliance on a small cluster of massive enterprise buyers creates severe operational vulnerability. Sudden strategic shifts within those client organizations can destroy smaller service providers.
This specific metric transitioned from an abstract theoretical risk into a quantified stock moving reality in early July. A prominent financial news report revealed that Meta Platforms was quietly developing its own internal cloud computing business. This massive initiative was internally designated as Meta Compute. The project aims to sell excess hardware capacity directly to outside enterprises.
The public market reaction was immediate and incredibly violent. Nebius stock plunged by as much as 17 percent in a single trading session. CoreWeave shares plummeted roughly 14 percent simultaneously. Neither company experienced any actual physical change to their underlying business fundamentals on that specific day. The brutal selloff was entirely driven by the sudden realization of deep concentration risk. Nebius and CoreWeave rely heavily on hyperscalers like Microsoft and Meta to consume their rented server capacity.
The stack layering thesis provided total insulation against this exact market event. Broadcom, Coherent, and Lumentum remained essentially untouched by the massive Meta Compute headlines. The physical hardware layers remain completely agnostic to the final operator of the data center. Meta must purchase custom silicon to build their systems. They must buy Tomahawk switches. They must procure optical transceivers regardless of whether they use the compute internally or rent it out commercially.
Coherent stands out as the most effectively diversified entity within the evaluated group. Historical corporate filings indicate no single customer accounts for more than 16 percent of their total revenue. Lumentum carries slightly more risk in this area. Broadcom maintains a highly stable but very notable concentration. Apple currently commands a 20 percent share of their sales.
❍ Investment Horizon and Timing
Understanding when the Vera Rubin catalyst impacts specific stock prices requires mapping the investment horizon for each distinct layer. These five companies do not move on the exact same timeline. Knowing when to enter and exit is just as important as knowing what to buy.
Layer 1 is a long term structural hold. Broadcom sits at the absolute foundation of the physical buildout. Their timeline stretches three to five years into the future. They possess massive multi year backlogs extending deep into 2031. Investors holding Broadcom should largely ignore short term quarter to quarter volatility in the cloud rental market. The thesis relies on the continuous multi year compounding of global data center upgrades.
Layer 2 is a distinct 12 to 24 month momentum trade. Coherent and Lumentum are currently experiencing extreme margin expansion purely due to a physical supply squeeze. The shortage of indium phosphide fabrication capacity will not last forever. Market analysts project that optical supply chain constraints will resolve over a multi year timeline as new fabrication plants come online. Investors should ride the pricing power wave now but prepare to exit once global manufacturing capacity catches up to hyperscaler demand.
Layer 3 is a highly volatile 6 to 12 month tactical trade. Nebius and CoreWeave operate at the very tip of the spear. Their valuations are wildly sensitive to immediate news headlines and hyperscaler spending decisions. The Meta Compute incident proved that a single press rumor can erase a month of gains in one afternoon. Investors in the compute layer must actively monitor the daily news cycle and adjust their positions rapidly based on short term capital flows.
❍ The Positioning Playbook
The research clearly outlines the "what" and the "why" of the Vera Rubin architecture. This final section provides the explicit framework on exactly "how" to execute this trade. Investors must align their specific risk tolerance with the correct vertical layer of the technology stack.
>> The Decision Matrix
If you want maximum leverage to early infrastructure spending and can tolerate massive daily price swings: Pick the Compute Layer. Buy NBIS or CRWV. These stocks provide direct exposure to the massive capital influx pouring into early cloud capacity. You must be willing to accept negative operating margins and extreme customer concentration risk in exchange for triple digit top line growth.If you want to capitalize on physical supply chain shortages with strong near term pricing power: Pick the Interconnect Layer. Buy COHR or LITE. These companies hold the specific optical components that the entire industry desperately needs right now. You must accept slightly less transparent backlog reporting in exchange for rapid margin expansion.If you want a highly mature balance sheet that collects massive cash flows regardless of who wins the cloud war: Pick the Silicon Layer. Buy AVGO. This is the lowest risk method to play the Vera Rubin catalyst. You accept lower headline growth percentages in exchange for a pristine 67 percent operating margin and deep contractual visibility.
>> Leading Indicators to Watch
Trailing financial metrics only tell you what already happened. To position yourself correctly for the next massive price movement, you must track forward looking indicators.
🟢 Indium Phosphide Pricing and Supply: The entire Layer 2 margin thesis rests on the current scarcity of indium phosphide substrates and advanced lasers. Track industry reports on wafer shipments and EML laser capacity. If supply catches up to demand faster than anticipated, the pricing power of Coherent and Lumentum will evaporate quickly.🔴 Hyperscaler Capital Expenditure Guidance: Nebius and CoreWeave rely entirely on massive tech companies continuing to spend billions of dollars on compute capacity. You must listen to the quarterly earnings calls of Microsoft, Google, and Meta. If these massive players announce any reduction in their future capital expenditure budgets, Layer 3 stocks will suffer immediate and violent selloffs.🟢 Nvidia Procurement Announcements: Watch where Nvidia deploys its corporate balance sheet. Their massive direct investments into Coherent, Lumentum, and Nebius explicitly signaled where they saw the biggest supply chain chokepoints. Any future announcements regarding Nvidia pre-paying for capacity or taking new equity stakes will immediately reprice the chosen supplier.
Deep Dive : The Nvidia Vera Rubin Narrative
The global technology sector is undergoing a massive infrastructure upgrade cycle. Artificial intelligence models require unprecedented computing power to function. Hardware designers must constantly innovate to meet these demands. The newest inflection point in this cycle is the Nvidia Vera Rubin platform. This architecture is the direct successor to the Blackwell generation. Vera Rubin represents a fundamental redesign of how modern data centers process information.
The entire platform centers around a newly engineered processing unit. This central component is the Rubin graphics processing unit. The Rubin chip uses a new generation of high bandwidth memory known as HBM4. This advanced memory architecture delivers extraordinary speeds. A single Rubin processor provides up to 288 gigabytes of HBM4 memory. The data transfer bandwidth reaches an astonishing 22 terabytes per second. This massive increase in memory speed is critical for running complex artificial intelligence tasks.
The Rubin processor requires a vast supporting cast of specialized hardware to function. Leading the charge is the Vera central processing unit, which handles complex data orchestration and host system management. Packed with 88 distinct custom Olympus ARM cores and 176 threads of spatial multithreading, Vera’s sole job is to keep the Rubin processors constantly fed with data so they never sit idle.
To connect these powerful chips without creating a massive communication bottleneck, the architecture uses the NVLink 6 switch. This interconnect provides direct physical pathways, delivering an incredible 3.6 terabytes per second of bandwidth per individual processor.
This blazing-fast connection allows dozens of separate chips to function seamlessly as a single computing brain. Nvidia packages these components into massive flagship rack systems known as the NVL72, where a single rack contains 72 Rubin processors, 36 Vera processors, and a total memory capacity hitting 20.7 terabytes.
Scaling beyond a single rack introduces severe physical bottlenecks. Connecting entire server farms requires advanced external networking hardware, and scaling up to 576 processors requires new systems like the Kyber NVL1152. Nvidia addresses these network limits with the Spectrum-X Ethernet system and co-packaged optics.
These components provide the massive scale-out fabric necessary for artificial intelligence factories. Because traditional copper cables degrade data signals rapidly over short distances at these extreme speeds, the architecture must transition to silicon photonics, using optical lasers to transmit data while reducing power consumption and lowering network latency.
The deployment of the Vera Rubin platform forces a massive shift across the entire technology sector, requiring complete supply chain mobilization. The rollout demands novel custom silicon designs, entirely new optical connective tissue, and unprecedented levels of physical cloud compute capacity, meaning investors cannot capture this shift by simply buying a single hardware stock.
This deployment requires a structured approach to the infrastructure stack. Positioning for this catalyst requires understanding exactly how capital flows from the end users down to the base component manufacturers.
❍ Core Company Profiles: The Vera Rubin Connection
>> NBIS (Nebius) Nebius serves as the direct physical deployment layer for the Vera Rubin architecture. The company buys the finished NVL72 racks and HBM4 components to build supercomputing clusters. Investors must care about Nebius because it translates raw Nvidia hardware into rentable cloud capacity. They act as the immediate end customer for the physical components. Their explosive revenue growth serves as a direct proxy for early stage Vera Rubin market demand. If Vera Rubin is a massive commercial success, Nebius captures the immediate rental revenue.
>> CRWV (CoreWeave) CoreWeave acts as an aggressive aggregator of Vera Rubin platforms. The firm secures massive debt to purchase the newest Rubin processors and networking switches. CoreWeave matters to this narrative because it pushes the architectural shift forward much faster than traditional public clouds. They convert the raw silicon innovations of Vera Rubin into recurring rental agreements for artificial intelligence laboratories. The company is actively building new global data centers specifically designed to house the extreme power density of these massive new server racks.
>> AVGO (Broadcom) Broadcom is the fundamental silicon bedrock supporting the Vera Rubin ecosystem. The company designs the custom accelerators and the Tomahawk networking switches required to bind tens of thousands of processors together. Investors must focus on Broadcom because massive Vera Rubin systems simply cannot function without these high speed networking chips. They provide a highly stable and mature way to profit from the physical transition. Broadcom collects immense revenue regardless of which cloud provider ultimately wins the compute war.
>> COHR (Coherent) Coherent provides the critical optical connective tissue required for Vera Rubin data speeds. The Rubin architecture moves data so fast that traditional copper cables fail over short distances. Coherent manufactures the necessary indium phosphide lasers and co-packaged optics. Investors should focus on Coherent because their components are an absolute physical requirement to build massive Vera Rubin server farms. Nvidia directly invested two billion dollars into Coherent specifically to secure this exact supply chain.
>> LITE (Lumentum) Lumentum supplies the high power continuous wave lasers essential for Vera Rubin scale up networking. The company physically enables the massive optical connections between individual processors. Lumentum is crucial to the catalyst because they hold the specific manufacturing capacity required to overcome severe optical supply bottlenecks. Nvidia also deployed a matching two billion dollar investment into Lumentum to guarantee access to these critical laser components for future infrastructure rollouts.
I. Positioning in the 3-Layer Stack
The deployment of the $NVDA Vera Rubin architecture requires a massive and highly complex supply chain. The five profiled companies provide structured exposure across three very distinct layers of a singular value chain. Evaluating these stocks requires a deep understanding of exactly where they sit within this hierarchy. Risk profiles behave very differently depending on the specific layer occupied. Profit margins face completely different structural pressures across each vertical level. Stack position sets the foundational frame that every other financial metric must be read through.
Layer 1 represents the pure Silicon foundation. Broadcom dominates this space. Broadcom designs custom artificial intelligence accelerators for hyperscale clients like Google and Meta. These custom chips serve as highly efficient alternatives to standard off the shelf graphics processing units. Broadcom builds the essential networking switches that physically connect these diverse processors. The company straddles both compute generation and physical networking design. This specific position is highly insulated from downstream volatility. Broadcom collects immense revenue regardless of which software application succeeds in the consumer market.
Layer 2 represents the Interconnect and Photonics segment. Coherent and Lumentum jointly occupy this critical space. These companies manufacture the optical transceivers and laser components that allow massive processor clusters to function as a single synchronized machine. They do not build the core computational processing chips. They do not operate the physical cloud data centers. They simply manufacture and sell the connective tissue. This layer currently faces a severe physical supply constraint regarding indium phosphide components. Indium phosphide is the base material required to manufacture the specific lasers used in high speed data transfer. This physical bottleneck is the direct cause of sharp recent margin expansion for both companies. The fundamental physics of data transfer at Vera Rubin speeds mandate specialized optical solutions.
Layer 3 represents the Compute and Cloud segment. Nebius and CoreWeave operate exclusively at this top level. These specialized neoclouds purchase the hardware produced by the lower foundational layers. They assemble the diverse components into finished compute capacity. They then rent this capacity out to enterprise clients. This layer sits closest to the actual algorithmic model training work. It is the most capital intensive tier of the entire stack. It is the least mature regarding pure operating profitability. Nebius and CoreWeave act as the primary end customers for the products designed by Broadcom, Coherent, and Lumentum. Positioning at this layer carries the absolute highest operational risk.
The structural reality of this three layer stack dictates overall investment strategy. The silicon and interconnect layers collect their payment upfront during the initial infrastructure buildout phase. They bear very little long term risk regarding the ultimate commercial viability of the end user applications. The compute layer pays heavily for physical capacity today in exchange for projected rental margins tomorrow.
II. Top-Line Growth Momentum
Revenue growth metrics provide a highly clear picture of current momentum within the supply chain. Growth rates must be analyzed relative to the base size of the specific company being evaluated. Raw percentages can obscure the actual scale of capital flowing through a business.
The tabulated data reveals a stark inverse relationship between the base size of the company and its headline growth rate. The newest and smallest infrastructure providers post the most explosive percentage numbers. Nebius achieved a massive 684 percent year over year revenue increase in its most recent quarter. CoreWeave delivered a staggering 112 percent growth on a much larger multibillion dollar base. These figures highlight the massive influx of capital pouring into Layer 3 of the infrastructure stack. Technology startups are aggressively booking compute capacity for future use. This drives immediate top line expansion for the specialized neocloud operators.
Broadcom presents a vastly more complex growth narrative. The company reported a 48 percent total year over year growth rate on its blended corporate book. This blended figure vastly understates the actual momentum of its specific artificial intelligence operations. The dedicated artificial intelligence segment within Broadcom grew at an incredible 143 percent year over year. This isolated segment growth perfectly matches the explosive acceleration seen in Layer 3 providers like CoreWeave. The market must parse these segments to understand the real hardware demand curve.
The photonics providers in Layer 2 show strong but varying momentum profiles. Lumentum reported impressive 90 percent year over year growth in the latest quarter. Coherent posted a more modest 21 percent increase during a similar period. This specific growth is heavily dictated by complex supply chain mechanics and manufacturing capacity constraints. The demand for optical transceivers outstrips the current global manufacturing supply. Their top line growth reflects their physical ability to produce units rather than any lack of end customer demand.
III. Operating Margin Trajectory
Revenue growth indicates general market momentum. Operating margins reveal the actual quality and long term sustainability of that specific growth. The fundamental unit economics behave drastically different depending on precise stack positioning. Fast growth often requires destroying near term profitability to secure future market share.
This specific parameter serves as the clearest statistical illustration of the entire layering thesis. The financial profiles of these individual companies directly reflect their physical operational roles. Broadcom operates with a highly mature and incredibly stable margin of 67 percent. The company incurs massive research and development costs upfront to design new chips. Selling high end networking chips at scale produces immense profit. Broadcom collects massive cash flows immediately upon physical product delivery to the end user.
CoreWeave presents a genuine and severe margin deterioration story. The company saw its adjusted operating margin collapse to a mere one percent. This represents a massive drop from 17 percent in the previous year. This severe contraction ties directly to massive front loaded capital expenditures. CoreWeave borrows tens of billions of dollars to purchase raw hardware and build vast physical data centers. The aggressive depreciation schedules and surging interest expenses drag down current profitability. Corporate management characterizes this current period as the absolute low point of their margin cycle.
Nebius displays highly similar financial dynamics. The company achieved a strong 45 percent adjusted EBITDA within its specific artificial intelligence cloud segment. The broader group operating income remains distinctly negative. Nebius currently navigates an intense hypergrowth capital expenditure phase. Building the physical infrastructure required to house massive new server clusters drains operating capital rapidly.
The Layer 2 photonics companies show real and highly profitable early stage margin inflections. Lumentum expanded its margin by an incredible 2,140 basis points year over year. Coherent maintains a steady climb toward 20.3 percent. This margin expansion is heavily driven by structural supply constraints across the broader tech industry. The global market lacks sufficient indium phosphide fabrication capacity. This deep shortage grants Coherent and Lumentum immense pricing power over their clients. Customers must pay significant premium rates to secure the optical transceivers necessary for their network deployments.
IV. Backlog and Revenue Visibility
Backlog metrics determine exactly how much of a company's future growth narrative is already contractually secured. This contrasts sharply with revenue that remains entirely speculative. High revenue visibility drastically reduces investment risk during turbulent macro market cycles.
CoreWeave and Broadcom provide the most rigorous and highly quantified backlog disclosures among the evaluated group. CoreWeave boasts a staggering 99.4 billion dollar forward revenue backlog. The company provides specific timelines for actual realization. They expect 36 percent fulfillment within two years. They project 75 percent fulfillment within four years. This massive contractual foundation allows CoreWeave to secure its vast debt financing.
Broadcom offers similarly transparent visibility to its investors. The company holds a 73 billion dollar backlog specifically tied to its artificial intelligence segment alone. The total performance obligations across the entire diversified corporate business reach an incredible 164.6 billion dollars. This unmatched forward visibility proves that the hyperscaler infrastructure buildout remains highly durable. The spending plans of major technology firms are completely well funded for the next several years.
Nebius showcases deep visibility despite its significantly smaller current revenue base. The company holds roughly 21.3 billion dollars in formal remaining performance obligations. The total contracted deal value stretches between 46 and 50 billion dollars. This massive value is largely anchored by binding agreements with Microsoft and Meta. These long term contracts extend deep into the year 2031.
A notable transparency gap exists within Layer 2. Coherent and Lumentum discuss their backlog with immense qualitative confidence. Coherent cites record backlog numbers stretching deep into calendar year 2028. Neither company publishes a comprehensive company wide dollar figure for their forward obligations. Investors must treat this total lack of numerical disclosure as a specific transparency gap.
V. Recent Catalysts
Trailing financial metrics only tell a small portion of the corporate story. Recent structural milestones and aggressive corporate actions heavily dictate short term momentum. These events validate long term operational strategies and signal shifts in the broader market landscape.
Two distinct patterns run across all five profiled companies. The first pattern is massive and deliberately directed capital intervention by Nvidia. Nvidia is aggressively taking direct equity stakes at multiple vertical levels of the infrastructure stack simultaneously. The hardware giant acquired a 9.3 percent equity stake in Nebius at the top compute layer. This formalizes a tight operational bond between the chip designer and the physical data center operator.
Simultaneously, Nvidia deployed four billion dollars directly into the middle Layer 2. They injected two billion dollars into Coherent. They injected two billion dollars into Lumentum. These targeted investments were immediately paired with multi year procurement commitments for advanced laser components. This specific behavior clearly outlines a strategy of total supply chain capture. Nvidia uses its massive corporate balance sheet to lock down the critical physical production capacity required for future rollouts.
The second major pattern involves aggressive global operational scaling. CoreWeave executed a major physical expansion into Europe by signing a strategic colocation deal with Conapto. This vital agreement places new compute capacity across two completely renewable powered data campuses in Stockholm. CoreWeave also signed a massive 335 million dollar storage agreement with Backblaze. This deal serves to offload lower tier data management tasks. This frees up premium server capacity for highly lucrative algorithmic training workloads.
Broadcom secured massive long term corporate stability by extending its custom chip partnership with Apple through the year 2031. This single contract firmly locks in roughly 20 percent of Broadcom corporate revenue for years. Lumentum responded directly to the optical supply bottleneck by rapidly acquiring a fifth indium phosphide fabrication facility in North Carolina. These diverse catalysts demonstrate a global supply chain moving rapidly to accommodate unprecedented physical scaling demands.
VI. Valuation Matrix
Valuation accurately contextualizes raw growth. Evaluating overall enterprise value against forward revenue projections provides a critical analytical filter. It determines whether a fundamentally high quality business actually represents a viable investment at its current market trading price.
The comprehensive valuation matrix reveals deep nuances beneath the headline numbers. Nebius and CoreWeave screen as the absolute cheapest assets relative to their sheer top line growth rates. Nebius carries an exceptionally low 0.021 comparative ratio. CoreWeave sits at a highly attractive 0.046 ratio. These metrics contain severe operational caveats.
The incredible 684 percent growth rate posted by Nebius occurs off an incredibly tiny baseline revenue figure. This specific rate of mathematical acceleration will fundamentally never repeat as the base denominator scales upward over time. CoreWeave appears exceptionally cheap on an enterprise value basis until structural debt is fully contextualized. Tens of billions of dollars in highly structured physical facility debt must be added back into the core calculation.
Broadcom appears relatively expensive when evaluating its purely blended corporate growth. The stock commands a massive 1.9 trillion dollar enterprise value. It currently trades at roughly 19 times forward revenue estimates. Applying the blended 48 percent growth rate yields a ratio of 0.40. The valuation becomes far more reasonable when isolated strictly to its artificial intelligence segment. The 143 percent segment growth rate drops the comparative ratio down to a highly attractive 0.13.
The middle optics layer presents a sharply split valuation dynamic. Coherent trades at a relatively modest 7.5 times forward revenue. Lumentum trades at a significantly richer 18.3 times forward revenue. This distinct premium valuation for Lumentum reflects the broader market rewarding its sharper near term margin expansion.
VII. Customer Concentration
Customer concentration represents a highly critical risk parameter. Heavy reliance on a small cluster of massive enterprise buyers creates severe operational vulnerability. Sudden strategic shifts within those client organizations can destroy smaller service providers.
This specific metric transitioned from an abstract theoretical risk into a quantified stock moving reality in early July. A prominent financial news report revealed that Meta Platforms was quietly developing its own internal cloud computing business. This massive initiative was internally designated as Meta Compute. The project aims to sell excess hardware capacity directly to outside enterprises.
The public market reaction was immediate and incredibly violent. Nebius stock plunged by as much as 17 percent in a single trading session. CoreWeave shares plummeted roughly 14 percent simultaneously. Neither company experienced any actual physical change to their underlying business fundamentals on that specific day. The brutal selloff was entirely driven by the sudden realization of deep concentration risk. Nebius and CoreWeave rely heavily on hyperscalers like Microsoft and Meta to consume their rented server capacity.
The stack layering thesis provided total insulation against this exact market event. Broadcom, Coherent, and Lumentum remained essentially untouched by the massive Meta Compute headlines. The physical hardware layers remain completely agnostic to the final operator of the data center. Meta must purchase custom silicon to build their systems. They must buy Tomahawk switches. They must procure optical transceivers regardless of whether they use the compute internally or rent it out commercially.
Coherent stands out as the most effectively diversified entity within the evaluated group. Historical corporate filings indicate no single customer accounts for more than 16 percent of their total revenue. Lumentum carries slightly more risk in this area. Broadcom maintains a highly stable but very notable concentration. Apple currently commands a 20 percent share of their sales.
❍ Investment Horizon and Timing
Understanding when the Vera Rubin catalyst impacts specific stock prices requires mapping the investment horizon for each distinct layer. These five companies do not move on the exact same timeline. Knowing when to enter and exit is just as important as knowing what to buy.
Layer 1 is a long term structural hold. Broadcom sits at the absolute foundation of the physical buildout. Their timeline stretches three to five years into the future. They possess massive multi year backlogs extending deep into 2031. Investors holding Broadcom should largely ignore short term quarter to quarter volatility in the cloud rental market. The thesis relies on the continuous multi year compounding of global data center upgrades.
Layer 2 is a distinct 12 to 24 month momentum trade. Coherent and Lumentum are currently experiencing extreme margin expansion purely due to a physical supply squeeze. The shortage of indium phosphide fabrication capacity will not last forever. Market analysts project that optical supply chain constraints will resolve over a multi year timeline as new fabrication plants come online. Investors should ride the pricing power wave now but prepare to exit once global manufacturing capacity catches up to hyperscaler demand.
Layer 3 is a highly volatile 6 to 12 month tactical trade. Nebius and CoreWeave operate at the very tip of the spear. Their valuations are wildly sensitive to immediate news headlines and hyperscaler spending decisions. The Meta Compute incident proved that a single press rumor can erase a month of gains in one afternoon. Investors in the compute layer must actively monitor the daily news cycle and adjust their positions rapidly based on short term capital flows.
❍ The Positioning Playbook
The research clearly outlines the "what" and the "why" of the Vera Rubin architecture. This final section provides the explicit framework on exactly "how" to execute this trade. Investors must align their specific risk tolerance with the correct vertical layer of the technology stack.
>> The Decision Matrix
If you want maximum leverage to early infrastructure spending and can tolerate massive daily price swings: Pick the Compute Layer. Buy NBIS or CRWV. These stocks provide direct exposure to the massive capital influx pouring into early cloud capacity. You must be willing to accept negative operating margins and extreme customer concentration risk in exchange for triple digit top line growth.If you want to capitalize on physical supply chain shortages with strong near term pricing power: Pick the Interconnect Layer. Buy COHR or LITE. These companies hold the specific optical components that the entire industry desperately needs right now. You must accept slightly less transparent backlog reporting in exchange for rapid margin expansion.If you want a highly mature balance sheet that collects massive cash flows regardless of who wins the cloud war: Pick the Silicon Layer. Buy AVGO. This is the lowest risk method to play the Vera Rubin catalyst. You accept lower headline growth percentages in exchange for a pristine 67 percent operating margin and deep contractual visibility.
>> Leading Indicators to Watch
Trailing financial metrics only tell you what already happened. To position yourself correctly for the next massive price movement, you must track forward looking indicators.
🟢 Indium Phosphide Pricing and Supply: The entire Layer 2 margin thesis rests on the current scarcity of indium phosphide substrates and advanced lasers. Track industry reports on wafer shipments and EML laser capacity. If supply catches up to demand faster than anticipated, the pricing power of Coherent and Lumentum will evaporate quickly.🔴 Hyperscaler Capital Expenditure Guidance: Nebius and CoreWeave rely entirely on massive tech companies continuing to spend billions of dollars on compute capacity. You must listen to the quarterly earnings calls of Microsoft, Google, and Meta. If these massive players announce any reduction in their future capital expenditure budgets, Layer 3 stocks will suffer immediate and violent selloffs.🟢 Nvidia Procurement Announcements: Watch where Nvidia deploys its corporate balance sheet. Their massive direct investments into Coherent, Lumentum, and Nebius explicitly signaled where they saw the biggest supply chain chokepoints. Any future announcements regarding Nvidia pre-paying for capacity or taking new equity stakes will immediately reprice the chosen supplier.
2
2
15
3.1k
PINNED
Article
Deep Dive: The Decentralised AI Model Training ArenaAs the master Leonardo da Vinci once said, "Learning never exhausts the mind." But in the age of artificial intelligence, it seems learning might just exhaust our planet's supply of computational power. The AI revolution, which is on track to pour over $15.7 trillion into the global economy by 2030, is fundamentally built on two things: data and the sheer force of computation. The problem is, the scale of AI models is growing at a blistering pace, with the compute needed for training doubling roughly every five months. This has created a massive bottleneck. A small handful of giant cloud companies hold the keys to the kingdom, controlling the GPU supply and creating a system that is expensive, permissioned, and frankly, a bit fragile for something so important.
This is where the story gets interesting. We're seeing a paradigm shift, an emerging arena called Decentralized AI (DeAI) model training, which uses the core ideas of blockchain and Web3 to challenge this centralized control.
Let's look at the numbers. The market for AI training data is set to hit around $3.5 billion by 2025, growing at a clip of about 25% each year. All that data needs processing. The Blockchain AI market itself is expected to be worth nearly $681 million in 2025, growing at a healthy 23% to 28% CAGR. And if we zoom out to the bigger picture, the whole Decentralized Physical Infrastructure (DePIN) space, which DeAI is a part of, is projected to blow past $32 billion in 2025.
What this all means is that AI's hunger for data and compute is creating a huge demand. DePIN and blockchain are stepping in to provide the supply, a global, open, and economically smart network for building intelligence. We've already seen how token incentives can get people to coordinate physical hardware like wireless hotspots and storage drives; now we're applying that same playbook to the most valuable digital production process in the world: creating artificial intelligence.
I. The DeAI Stack
The push for decentralized AI stems from a deep philosophical mission to build a more open, resilient, and equitable AI ecosystem. It's about fostering innovation and resisting the concentration of power that we see today. Proponents often contrast two ways of organizing the world: a "Taxis," which is a centrally designed and controlled order, versus a "Cosmos," a decentralized, emergent order that grows from autonomous interactions.
A centralized approach to AI could create a sort of "autocomplete for life," where AI systems subtly nudge human actions and, choice by choice, wear away our ability to think for ourselves. Decentralization is the proposed antidote. It's a framework where AI is a tool to enhance human flourishing, not direct it. By spreading out control over data, models, and compute, DeAI aims to put power back into the hands of users, creators, and communities, making sure the future of intelligence is something we share, not something a few companies own.
II. Deconstructing the DeAI Stack
At its heart, you can break AI down into three basic pieces: data, compute, and algorithms. The DeAI movement is all about rebuilding each of these pillars on a decentralized foundation.
❍ Pillar 1: Decentralized Data
The fuel for any powerful AI is a massive and varied dataset. In the old model, this data gets locked away in centralized systems like Amazon Web Services or Google Cloud. This creates single points of failure, censorship risks, and makes it hard for newcomers to get access. Decentralized storage networks provide an alternative, offering a permanent, censorship-resistant, and verifiable home for AI training data.
Projects like Filecoin and Arweave are key players here. Filecoin uses a global network of storage providers, incentivizing them with tokens to reliably store data. It uses clever cryptographic proofs like Proof-of-Replication and Proof-of-Spacetime to make sure the data is safe and available. Arweave has a different take: you pay once, and your data is stored forever on an immutable "permaweb". By turning data into a public good, these networks create a solid, transparent foundation for AI development, ensuring the datasets used for training are secure and open to everyone.
❍ Pillar 2: Decentralized Compute
The biggest setback in AI right now is getting access to high-performance compute, especially GPUs. DeAI tackles this head-on by creating protocols that can gather and coordinate compute power from all over the world, from consumer-grade GPUs in people's homes to idle machines in data centers. This turns computational power from a scarce resource you rent from a few gatekeepers into a liquid, global commodity. Projects like Prime Intellect, Gensyn, and Nous Research are building the marketplaces for this new compute economy.
❍ Pillar 3: Decentralized Algorithms & Models
Getting the data and compute is one thing. The real work is in coordinating the process of training, making sure the work is done correctly, and getting everyone to collaborate in an environment where you can't necessarily trust anyone. This is where a mix of Web3 technologies comes together to form the operational core of DeAI.
Blockchain & Smart Contracts: Think of these as the unchangeable and transparent rulebook. Blockchains provide a shared ledger to track who did what, and smart contracts automatically enforce the rules and hand out rewards, so you don't need a middleman.Federated Learning: This is a key privacy-preserving technique. It lets AI models train on data scattered across different locations without the data ever having to move. Only the model updates get shared, not your personal information, which keeps user data private and secure.Tokenomics: This is the economic engine. Tokens create a mini-economy that rewards people for contributing valuable things, be it data, compute power, or improvements to the AI models. It gets everyone's incentives aligned toward the shared goal of building better AI.
The beauty of this stack is its modularity. An AI developer could grab a dataset from Arweave, use Gensyn's network for verifiable training, and then deploy the finished model on a specialized Bittensor subnet to make money. This interoperability turns the pieces of AI development into "intelligence legos," sparking a much more dynamic and innovative ecosystem than any single, closed platform ever could.
III. How Decentralized Model Training Works
Imagine the goal is to create a world-class AI chef. The old, centralized way is to lock one apprentice in a single, secret kitchen (like Google's) with a giant, secret cookbook. The decentralized way, using a technique called Federated Learning, is more like running a global cooking club.
The master recipe (the "global model") is sent to thousands of local chefs all over the world. Each chef tries the recipe in their own kitchen, using their unique local ingredients and methods ("local data"). They don't share their secret ingredients; they just make notes on how to improve the recipe ("model updates"). These notes are sent back to the club headquarters. The club then combines all the notes to create a new, improved master recipe, which gets sent out for the next round. The whole thing is managed by a transparent, automated club charter (the "blockchain"), which makes sure every chef who helps out gets credit and is rewarded fairly ("token rewards").
❍ Key Mechanisms
That analogy maps pretty closely to the technical workflow that allows for this kind of collaborative training. It’s a complex thing, but it boils down to a few key mechanisms that make it all possible.
Distributed Data Parallelism: This is the starting point. Instead of one giant computer crunching one massive dataset, the dataset is broken up into smaller pieces and distributed across many different computers (nodes) in the network. Each of these nodes gets a complete copy of the AI model to work with. This allows for a huge amount of parallel processing, dramatically speeding things up. Each node trains its model replica on its unique slice of data.Low-Communication Algorithms: A major challenge is keeping all those model replicas in sync without clogging the internet. If every node had to constantly broadcast every tiny update to every other node, it would be incredibly slow and inefficient. This is where low-communication algorithms come in. Techniques like DiLoCo (Distributed Low-Communication) allow nodes to perform hundreds of local training steps on their own before needing to synchronize their progress with the wider network. Newer methods like NoLoCo (No-all-reduce Low-Communication) go even further, replacing massive group synchronizations with a "gossip" method where nodes just periodically average their updates with a single, randomly chosen peer.Compression: To further reduce the communication burden, networks use compression techniques. This is like zipping a file before you email it. Model updates, which are just big lists of numbers, can be compressed to make them smaller and faster to send. Quantization, for example, reduces the precision of these numbers (say, from a 32-bit float to an 8-bit integer), which can shrink the data size by a factor of four or more with minimal impact on accuracy. Pruning is another method that removes unimportant connections within the model, making it smaller and more efficient.Incentive and Validation: In a trustless network, you need to make sure everyone plays fair and gets rewarded for their work. This is the job of the blockchain and its token economy. Smart contracts act as automated escrow, holding and distributing token rewards to participants who contribute useful compute or data. To prevent cheating, networks use validation mechanisms. This can involve validators randomly re-running a small piece of a node's computation to verify its correctness or using cryptographic proofs to ensure the integrity of the results. This creates a system of "Proof-of-Intelligence" where valuable contributions are verifiably rewarded.Fault Tolerance: Decentralized networks are made up of unreliable, globally distributed computers. Nodes can drop offline at any moment. The system needs to be ableto handle this without the whole training process crashing. This is where fault tolerance comes in. Frameworks like Prime Intellect's ElasticDeviceMesh allow nodes to dynamically join or leave a training run without causing a system-wide failure. Techniques like asynchronous checkpointing regularly save the model's progress, so if a node fails, the network can quickly recover from the last saved state instead of starting from scratch.
This continuous, iterative workflow fundamentally changes what an AI model is. It's no longer a static object created and owned by one company. It becomes a living system, a consensus state that is constantly being refined by a global collective. The model isn't a product; it's a protocol, collectively maintained and secured by its network.
IV. Decentralized Training Protocols
The theoretical framework of decentralized AI is now being implemented by a growing number of innovative projects, each with a unique strategy and technical approach. These protocols create a competitive arena where different models of collaboration, verification, and incentivization are being tested at scale.
❍ The Modular Marketplace: Bittensor's Subnet Ecosystem
Bittensor operates as an "internet of digital commodities," a meta-protocol hosting numerous specialized "subnets." Each subnet is a competitive, incentive-driven market for a specific AI task, from text generation to protein folding. Within this ecosystem, two subnets are particularly relevant to decentralized training.
Templar (Subnet 3) is focused on creating a permissionless and antifragile platform for decentralized pre-training. It embodies a pure, competitive approach where miners train models (currently up to 8 billion parameters, with a roadmap toward 70 billion) and are rewarded based on performance, driving a relentless race to produce the best possible intelligence.
Macrocosmos (Subnet 9) represents a significant evolution with its IOTA (Incentivised Orchestrated Training Architecture). IOTA moves beyond isolated competition toward orchestrated collaboration. It employs a hub-and-spoke architecture where an Orchestrator coordinates data- and pipeline-parallel training across a network of miners. Instead of each miner training an entire model, they are assigned specific layers of a much larger model. This division of labor allows the collective to train models at a scale far beyond the capacity of any single participant. Validators perform "shadow audits" to verify work, and a granular incentive system rewards contributions fairly, fostering a collaborative yet accountable environment.
❍ The Verifiable Compute Layer: Gensyn's Trustless Network
Gensyn's primary focus is on solving one of the hardest problems in the space: verifiable machine learning. Its protocol, built as a custom Ethereum L2 Rollup, is designed to provide cryptographic proof of correctness for deep learning computations performed on untrusted nodes.
A key innovation from Gensyn's research is NoLoCo (No-all-reduce Low-Communication), a novel optimization method for distributed training. Traditional methods require a global "all-reduce" synchronization step, which creates a bottleneck, especially on low-bandwidth networks. NoLoCo eliminates this step entirely. Instead, it uses a gossip-based protocol where nodes periodically average their model weights with a single, randomly selected peer. This, combined with a modified Nesterov momentum optimizer and random routing of activations, allows the network to converge efficiently without global synchronization, making it ideal for training over heterogeneous, internet-connected hardware. Gensyn's RL Swarm testnet application demonstrates this stack in action, enabling collaborative reinforcement learning in a decentralized setting.
❍ The Global Compute Aggregator: Prime Intellect's Open Framework
Prime Intellect is building a peer-to-peer protocol to aggregate global compute resources into a unified marketplace, effectively creating an "Airbnb for compute". Their PRIME framework is engineered for fault-tolerant, high-performance training on a network of unreliable and globally distributed workers.
The framework is built on an adapted version of the DiLoCo (Distributed Low-Communication) algorithm, which allows nodes to perform many local training steps before requiring a less frequent global synchronization. Prime Intellect has augmented this with significant engineering breakthroughs. The ElasticDeviceMesh allows nodes to dynamically join or leave a training run without crashing the system. Asynchronous checkpointing to RAM-backed filesystems minimizes downtime. Finally, they developed custom int8 all-reduce kernels, which reduce the communication payload during synchronization by a factor of four, drastically lowering bandwidth requirements. This robust technical stack enabled them to successfully orchestrate the world's first decentralized training of a 10-billion-parameter model, INTELLECT-1.
❍ The Open-Source Collective: Nous Research's Community-Driven Approach
Nous Research operates as a decentralized AI research collective with a strong open-source ethos, building its infrastructure on the Solana blockchain for its high throughput and low transaction costs.
Their flagship platform, Nous Psyche, is a decentralized training network powered by two core technologies: DisTrO (Distributed Training Over-the-Internet) and its underlying optimization algorithm, DeMo (Decoupled Momentum Optimization). Developed in collaboration with an OpenAI co-founder, these technologies are designed for extreme bandwidth efficiency, claiming a reduction of 1,000x to 10,000x compared to conventional methods. This breakthrough makes it feasible to participate in large-scale model training using consumer-grade GPUs and standard internet connections, radically democratizing access to AI development.
❍ The Pluralistic Future: Pluralis AI's Protocol Learning
Pluralis AI is tackling a higher-level challenge: not just how to train models, but how to align them with diverse and pluralistic human values in a privacy-preserving manner.
Their PluralLLM framework introduces a federated learning-based approach to preference alignment, a task traditionally handled by centralized methods like Reinforcement Learning from Human Feedback (RLHF). With PluralLLM, different user groups can collaboratively train a preference predictor model without ever sharing their sensitive, underlying preference data. The framework uses Federated Averaging to aggregate these preference updates, achieving faster convergence and better alignment scores than centralized methods while preserving both privacy and fairness.
Their overarching concept of Protocol Learning further ensures that no single participant can obtain the complete model, solving critical intellectual property and trust issues inherent in collaborative AI development.
While the decentralized AI training arena holds a promising Future, its path to mainstream adoption is filled with significant challenges. The technical complexity of managing and synchronizing computations across thousands of unreliable nodes remains a formidable engineering hurdle. Furthermore, the lack of clear legal and regulatory frameworks for decentralized autonomous systems and collectively owned intellectual property creates uncertainty for developers and investors alike.
Ultimately, for these networks to achieve long-term viability, they must evolve beyond speculation and attract real, paying customers for their computational services, thereby generating sustainable, protocol-driven revenue. And we believe they'll eventually cross the road even before our speculation.
Deep Dive: The Decentralised AI Model Training Arena
As the master Leonardo da Vinci once said, "Learning never exhausts the mind." But in the age of artificial intelligence, it seems learning might just exhaust our planet's supply of computational power. The AI revolution, which is on track to pour over $15.7 trillion into the global economy by 2030, is fundamentally built on two things: data and the sheer force of computation. The problem is, the scale of AI models is growing at a blistering pace, with the compute needed for training doubling roughly every five months. This has created a massive bottleneck. A small handful of giant cloud companies hold the keys to the kingdom, controlling the GPU supply and creating a system that is expensive, permissioned, and frankly, a bit fragile for something so important.
This is where the story gets interesting. We're seeing a paradigm shift, an emerging arena called Decentralized AI (DeAI) model training, which uses the core ideas of blockchain and Web3 to challenge this centralized control.
Let's look at the numbers. The market for AI training data is set to hit around $3.5 billion by 2025, growing at a clip of about 25% each year. All that data needs processing. The Blockchain AI market itself is expected to be worth nearly $681 million in 2025, growing at a healthy 23% to 28% CAGR. And if we zoom out to the bigger picture, the whole Decentralized Physical Infrastructure (DePIN) space, which DeAI is a part of, is projected to blow past $32 billion in 2025.
What this all means is that AI's hunger for data and compute is creating a huge demand. DePIN and blockchain are stepping in to provide the supply, a global, open, and economically smart network for building intelligence. We've already seen how token incentives can get people to coordinate physical hardware like wireless hotspots and storage drives; now we're applying that same playbook to the most valuable digital production process in the world: creating artificial intelligence.
I. The DeAI Stack
The push for decentralized AI stems from a deep philosophical mission to build a more open, resilient, and equitable AI ecosystem. It's about fostering innovation and resisting the concentration of power that we see today. Proponents often contrast two ways of organizing the world: a "Taxis," which is a centrally designed and controlled order, versus a "Cosmos," a decentralized, emergent order that grows from autonomous interactions.
A centralized approach to AI could create a sort of "autocomplete for life," where AI systems subtly nudge human actions and, choice by choice, wear away our ability to think for ourselves. Decentralization is the proposed antidote. It's a framework where AI is a tool to enhance human flourishing, not direct it. By spreading out control over data, models, and compute, DeAI aims to put power back into the hands of users, creators, and communities, making sure the future of intelligence is something we share, not something a few companies own.
II. Deconstructing the DeAI Stack
At its heart, you can break AI down into three basic pieces: data, compute, and algorithms. The DeAI movement is all about rebuilding each of these pillars on a decentralized foundation.
❍ Pillar 1: Decentralized Data
The fuel for any powerful AI is a massive and varied dataset. In the old model, this data gets locked away in centralized systems like Amazon Web Services or Google Cloud. This creates single points of failure, censorship risks, and makes it hard for newcomers to get access. Decentralized storage networks provide an alternative, offering a permanent, censorship-resistant, and verifiable home for AI training data.
Projects like Filecoin and Arweave are key players here. Filecoin uses a global network of storage providers, incentivizing them with tokens to reliably store data. It uses clever cryptographic proofs like Proof-of-Replication and Proof-of-Spacetime to make sure the data is safe and available. Arweave has a different take: you pay once, and your data is stored forever on an immutable "permaweb". By turning data into a public good, these networks create a solid, transparent foundation for AI development, ensuring the datasets used for training are secure and open to everyone.
❍ Pillar 2: Decentralized Compute
The biggest setback in AI right now is getting access to high-performance compute, especially GPUs. DeAI tackles this head-on by creating protocols that can gather and coordinate compute power from all over the world, from consumer-grade GPUs in people's homes to idle machines in data centers. This turns computational power from a scarce resource you rent from a few gatekeepers into a liquid, global commodity. Projects like Prime Intellect, Gensyn, and Nous Research are building the marketplaces for this new compute economy.
❍ Pillar 3: Decentralized Algorithms & Models
Getting the data and compute is one thing. The real work is in coordinating the process of training, making sure the work is done correctly, and getting everyone to collaborate in an environment where you can't necessarily trust anyone. This is where a mix of Web3 technologies comes together to form the operational core of DeAI.
Blockchain & Smart Contracts: Think of these as the unchangeable and transparent rulebook. Blockchains provide a shared ledger to track who did what, and smart contracts automatically enforce the rules and hand out rewards, so you don't need a middleman.Federated Learning: This is a key privacy-preserving technique. It lets AI models train on data scattered across different locations without the data ever having to move. Only the model updates get shared, not your personal information, which keeps user data private and secure.Tokenomics: This is the economic engine. Tokens create a mini-economy that rewards people for contributing valuable things, be it data, compute power, or improvements to the AI models. It gets everyone's incentives aligned toward the shared goal of building better AI.
The beauty of this stack is its modularity. An AI developer could grab a dataset from Arweave, use Gensyn's network for verifiable training, and then deploy the finished model on a specialized Bittensor subnet to make money. This interoperability turns the pieces of AI development into "intelligence legos," sparking a much more dynamic and innovative ecosystem than any single, closed platform ever could.
III. How Decentralized Model Training Works
Imagine the goal is to create a world-class AI chef. The old, centralized way is to lock one apprentice in a single, secret kitchen (like Google's) with a giant, secret cookbook. The decentralized way, using a technique called Federated Learning, is more like running a global cooking club.
The master recipe (the "global model") is sent to thousands of local chefs all over the world. Each chef tries the recipe in their own kitchen, using their unique local ingredients and methods ("local data"). They don't share their secret ingredients; they just make notes on how to improve the recipe ("model updates"). These notes are sent back to the club headquarters. The club then combines all the notes to create a new, improved master recipe, which gets sent out for the next round. The whole thing is managed by a transparent, automated club charter (the "blockchain"), which makes sure every chef who helps out gets credit and is rewarded fairly ("token rewards").
❍ Key Mechanisms
That analogy maps pretty closely to the technical workflow that allows for this kind of collaborative training. It’s a complex thing, but it boils down to a few key mechanisms that make it all possible.
Distributed Data Parallelism: This is the starting point. Instead of one giant computer crunching one massive dataset, the dataset is broken up into smaller pieces and distributed across many different computers (nodes) in the network. Each of these nodes gets a complete copy of the AI model to work with. This allows for a huge amount of parallel processing, dramatically speeding things up. Each node trains its model replica on its unique slice of data.Low-Communication Algorithms: A major challenge is keeping all those model replicas in sync without clogging the internet. If every node had to constantly broadcast every tiny update to every other node, it would be incredibly slow and inefficient. This is where low-communication algorithms come in. Techniques like DiLoCo (Distributed Low-Communication) allow nodes to perform hundreds of local training steps on their own before needing to synchronize their progress with the wider network. Newer methods like NoLoCo (No-all-reduce Low-Communication) go even further, replacing massive group synchronizations with a "gossip" method where nodes just periodically average their updates with a single, randomly chosen peer.Compression: To further reduce the communication burden, networks use compression techniques. This is like zipping a file before you email it. Model updates, which are just big lists of numbers, can be compressed to make them smaller and faster to send. Quantization, for example, reduces the precision of these numbers (say, from a 32-bit float to an 8-bit integer), which can shrink the data size by a factor of four or more with minimal impact on accuracy. Pruning is another method that removes unimportant connections within the model, making it smaller and more efficient.Incentive and Validation: In a trustless network, you need to make sure everyone plays fair and gets rewarded for their work. This is the job of the blockchain and its token economy. Smart contracts act as automated escrow, holding and distributing token rewards to participants who contribute useful compute or data. To prevent cheating, networks use validation mechanisms. This can involve validators randomly re-running a small piece of a node's computation to verify its correctness or using cryptographic proofs to ensure the integrity of the results. This creates a system of "Proof-of-Intelligence" where valuable contributions are verifiably rewarded.Fault Tolerance: Decentralized networks are made up of unreliable, globally distributed computers. Nodes can drop offline at any moment. The system needs to be ableto handle this without the whole training process crashing. This is where fault tolerance comes in. Frameworks like Prime Intellect's ElasticDeviceMesh allow nodes to dynamically join or leave a training run without causing a system-wide failure. Techniques like asynchronous checkpointing regularly save the model's progress, so if a node fails, the network can quickly recover from the last saved state instead of starting from scratch.
This continuous, iterative workflow fundamentally changes what an AI model is. It's no longer a static object created and owned by one company. It becomes a living system, a consensus state that is constantly being refined by a global collective. The model isn't a product; it's a protocol, collectively maintained and secured by its network.
IV. Decentralized Training Protocols
The theoretical framework of decentralized AI is now being implemented by a growing number of innovative projects, each with a unique strategy and technical approach. These protocols create a competitive arena where different models of collaboration, verification, and incentivization are being tested at scale.
❍ The Modular Marketplace: Bittensor's Subnet Ecosystem
Bittensor operates as an "internet of digital commodities," a meta-protocol hosting numerous specialized "subnets." Each subnet is a competitive, incentive-driven market for a specific AI task, from text generation to protein folding. Within this ecosystem, two subnets are particularly relevant to decentralized training.
Templar (Subnet 3) is focused on creating a permissionless and antifragile platform for decentralized pre-training. It embodies a pure, competitive approach where miners train models (currently up to 8 billion parameters, with a roadmap toward 70 billion) and are rewarded based on performance, driving a relentless race to produce the best possible intelligence.
Macrocosmos (Subnet 9) represents a significant evolution with its IOTA (Incentivised Orchestrated Training Architecture). IOTA moves beyond isolated competition toward orchestrated collaboration. It employs a hub-and-spoke architecture where an Orchestrator coordinates data- and pipeline-parallel training across a network of miners. Instead of each miner training an entire model, they are assigned specific layers of a much larger model. This division of labor allows the collective to train models at a scale far beyond the capacity of any single participant. Validators perform "shadow audits" to verify work, and a granular incentive system rewards contributions fairly, fostering a collaborative yet accountable environment.
❍ The Verifiable Compute Layer: Gensyn's Trustless Network
Gensyn's primary focus is on solving one of the hardest problems in the space: verifiable machine learning. Its protocol, built as a custom Ethereum L2 Rollup, is designed to provide cryptographic proof of correctness for deep learning computations performed on untrusted nodes.
A key innovation from Gensyn's research is NoLoCo (No-all-reduce Low-Communication), a novel optimization method for distributed training. Traditional methods require a global "all-reduce" synchronization step, which creates a bottleneck, especially on low-bandwidth networks. NoLoCo eliminates this step entirely. Instead, it uses a gossip-based protocol where nodes periodically average their model weights with a single, randomly selected peer. This, combined with a modified Nesterov momentum optimizer and random routing of activations, allows the network to converge efficiently without global synchronization, making it ideal for training over heterogeneous, internet-connected hardware. Gensyn's RL Swarm testnet application demonstrates this stack in action, enabling collaborative reinforcement learning in a decentralized setting.
❍ The Global Compute Aggregator: Prime Intellect's Open Framework
Prime Intellect is building a peer-to-peer protocol to aggregate global compute resources into a unified marketplace, effectively creating an "Airbnb for compute". Their PRIME framework is engineered for fault-tolerant, high-performance training on a network of unreliable and globally distributed workers.
The framework is built on an adapted version of the DiLoCo (Distributed Low-Communication) algorithm, which allows nodes to perform many local training steps before requiring a less frequent global synchronization. Prime Intellect has augmented this with significant engineering breakthroughs. The ElasticDeviceMesh allows nodes to dynamically join or leave a training run without crashing the system. Asynchronous checkpointing to RAM-backed filesystems minimizes downtime. Finally, they developed custom int8 all-reduce kernels, which reduce the communication payload during synchronization by a factor of four, drastically lowering bandwidth requirements. This robust technical stack enabled them to successfully orchestrate the world's first decentralized training of a 10-billion-parameter model, INTELLECT-1.
❍ The Open-Source Collective: Nous Research's Community-Driven Approach
Nous Research operates as a decentralized AI research collective with a strong open-source ethos, building its infrastructure on the Solana blockchain for its high throughput and low transaction costs.
Their flagship platform, Nous Psyche, is a decentralized training network powered by two core technologies: DisTrO (Distributed Training Over-the-Internet) and its underlying optimization algorithm, DeMo (Decoupled Momentum Optimization). Developed in collaboration with an OpenAI co-founder, these technologies are designed for extreme bandwidth efficiency, claiming a reduction of 1,000x to 10,000x compared to conventional methods. This breakthrough makes it feasible to participate in large-scale model training using consumer-grade GPUs and standard internet connections, radically democratizing access to AI development.
❍ The Pluralistic Future: Pluralis AI's Protocol Learning
Pluralis AI is tackling a higher-level challenge: not just how to train models, but how to align them with diverse and pluralistic human values in a privacy-preserving manner.
Their PluralLLM framework introduces a federated learning-based approach to preference alignment, a task traditionally handled by centralized methods like Reinforcement Learning from Human Feedback (RLHF). With PluralLLM, different user groups can collaboratively train a preference predictor model without ever sharing their sensitive, underlying preference data. The framework uses Federated Averaging to aggregate these preference updates, achieving faster convergence and better alignment scores than centralized methods while preserving both privacy and fairness.
Their overarching concept of Protocol Learning further ensures that no single participant can obtain the complete model, solving critical intellectual property and trust issues inherent in collaborative AI development.
While the decentralized AI training arena holds a promising Future, its path to mainstream adoption is filled with significant challenges. The technical complexity of managing and synchronizing computations across thousands of unreliable nodes remains a formidable engineering hurdle. Furthermore, the lack of clear legal and regulatory frameworks for decentralized autonomous systems and collectively owned intellectual property creates uncertainty for developers and investors alike.
Ultimately, for these networks to achieve long-term viability, they must evolve beyond speculation and attract real, paying customers for their computational services, thereby generating sustainable, protocol-driven revenue. And we believe they'll eventually cross the road even before our speculation.
13
11
94
14.3k
🟡 𝐁𝐍𝐁 𝐂𝐡𝐚𝐢𝐧 𝐃𝐚𝐢𝐥𝐲 𝐑𝐞𝐜𝐚𝐩 | 𝐋𝐚𝐬𝐭 24𝐇 $BNB
-
• Changer+ launched its self-custodial stablecoin wallet, adding native support for BNB Chain, USDT and USDC alongside Ethereum, TRON and $SOL Solana. New users get 3 fee-covered transactions on BNB Chain from Oct. 6 to Nov. 6.
• BNB Chain processed 16.71M transactions in the latest 24H, with 2.25M active addresses and 406,188 new addresses. DEX volume reached about $794M, while chain fees were roughly $589K.
• BNB Chain’s stablecoin supply is currently around $13.31B, with USDT accounting for 69.01%. The chain generated roughly $58.9K in protocol revenue and $1.18M in app revenue over 24H.
• BNB Chain DEX liquidity sits around $3.55B, according to the latest live tracker, with more than 4.1M transactions in 24H.
1
173
$POL ; The Dumbest Marketing Team Ever existed in Crypto. When Your Project is Half dead and hovering around Polymarket Deak , Don't play these moves.
Trying to be oversmart and Find Out : -5% Dump For Nothing , Literally Nothing .
$POL ; The Dumbest Marketing Team Ever existed in Crypto. When Your Project is Half dead and hovering around Polymarket Deak , Don't play these moves.
Trying to be oversmart and Find Out : -5% Dump For Nothing , Literally Nothing .
Trying to be oversmart and Find Out : -5% Dump For Nothing , Literally Nothing .
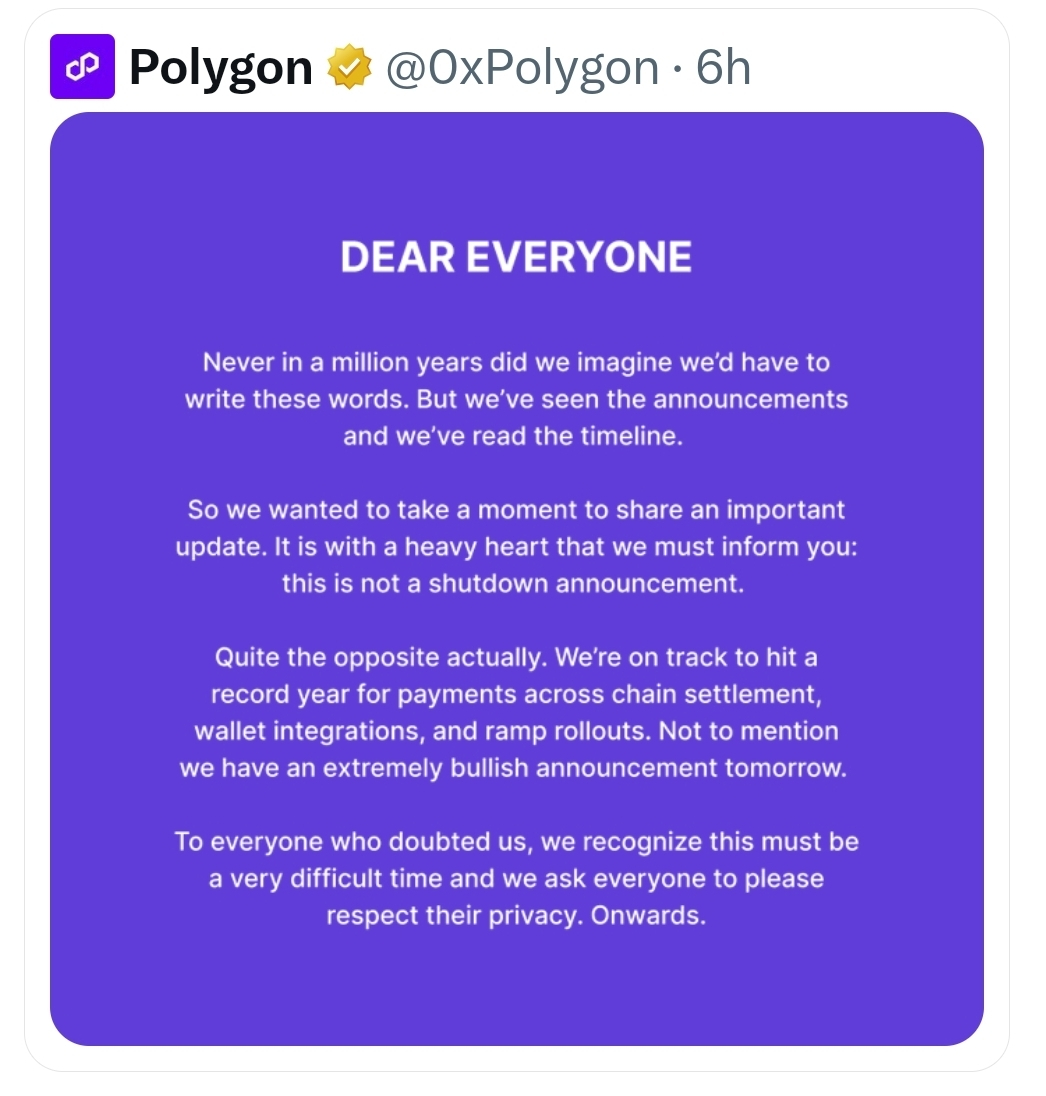
1
246
Article
What Nillion Actually DoesPrivacy has always had a problem on the internet: the moment you want software to do something useful with your data, you usually have to give that software access to the data itself.
That trade-off was manageable when most software was simple. You searched for something, opened a website, sent an email, or uploaded a document. But the internet is changing rapidly. AI systems are becoming more personalized, applications are becoming more autonomous, and AI agents are expected to work with increasingly sensitive information. The more useful these systems become, the more context they need. And much of that context is private.
Your financial information is private. Your medical records are private. Your work documents are private. Your personal conversations are private. Even something as simple as your preferences, browsing history, or instructions to an AI can reveal a surprising amount about you.
So we have a problem.
We want software to use more of our data, but we don't necessarily want the software infrastructure processing that data to see everything inside it.
This is where Nillion comes in.
Nillion is building what it calls a Blind Computer, a decentralized network designed to store and process sensitive information while keeping that information protected from application backends and the operators running the underlying infrastructure. Its central idea is straightforward: make data usable without requiring the raw data to be exposed.
That sounds simple.
The technology underneath it is not.
The Problem Nillion Is Trying to Solve
Most modern applications follow a familiar model. You provide some information, the application sends it to a backend, the backend processes it, and you receive a result.
For example, imagine uploading a private document to an AI application and asking:
"Summarize this document and tell me what I need to do next."
The AI needs to process the document to answer your question. Traditionally, that means the service needs access to the document in a form it can actually read and compute over.
That creates a trust relationship.
You are effectively saying:
"Here is my sensitive information. I trust your infrastructure to process it correctly, protect it from unauthorized access, and not expose it."
Encryption helps protect information while it is being transmitted or sitting in storage. But historically, there has been a difficult point in the middle: computation.
At some point, the system has to do something with the data.
The traditional pattern is essentially:
Encrypt → Decrypt → Compute → Encrypt again.
The problem is that during the computation stage, the information may exist in a form that the infrastructure can potentially access.
Nillion is trying to change that model.
Its Blind Computer combines privacy-enhancing technologies such as secure multi-party computation, homomorphic encryption and trusted execution environments to allow sensitive information to be stored and processed while reducing the need to expose the underlying data to infrastructure operators.
The philosophical shift is important.
Instead of saying:
"Trust us with your data."
The goal becomes:
"Trust the technology protecting the computation."
Think of Nillion as a Privacy Layer for Computation
One of the easiest ways to misunderstand Nillion is to think of it as simply another blockchain.
That's not really the interesting part.
Blockchains are exceptionally good at creating shared, transparent state between parties that do not necessarily trust each other. But transparency is not always desirable. There are plenty of situations where you want the result of a computation to be useful without exposing all of the information that produced that result.
Nillion is targeting that other side of the equation.
Blockchains made it possible to coordinate without trusting a central intermediary. Nillion is trying to make computation possible without exposing sensitive information to the infrastructure performing it.
That makes the concept particularly interesting in a world where AI is becoming more important.
An AI model is only as useful as the context it receives.
Give an AI generic information and you get a generic assistant.
Give it your actual documents, preferences, financial information, work history, personal goals and other context, and it can potentially become much more useful.
But that creates an uncomfortable question:
How much of your life are you willing to hand over to an AI provider?
Nillion's answer is to build infrastructure where sensitive information can remain protected while still being used by applications.
That is the bigger idea behind the Blind Computer.
Enter Nillion
This is where Nillion's core proposition becomes clearer.
The goal isn't to stop applications from using sensitive information. It is to change how that information is made available to computation.
Instead of treating privacy as a feature added at the end, Nillion wants privacy to exist inside the computing infrastructure itself.
The result Nillion is aiming for can be summarized very simply:
Protect the input.
Compute privately.
Reveal only the useful result.
That sounds straightforward, but achieving it requires several different technologies and infrastructure components working together.
How Does Nillion Actually Do It?
Nillion doesn't rely on one single privacy technology. Its current Blind Computer stack is divided into different modules that handle different parts of the problem.
Three of the most important are nilDB, nilCC and nilAI.
At a high level, the process looks something like this:
Your sensitive information → protected infrastructure → private computation → useful result
The important part is that the application doesn't need to treat the underlying raw information as ordinary, openly accessible server data throughout the process.
That is what makes Nillion different from simply putting another database behind an application.
nilDB: Private Storage
nilDB is Nillion's private storage layer. Data can be encrypted and split into secret shares before those shares are distributed across multiple nodes. The idea is that an individual node should not be able to simply look at the complete original information sitting inside the system.
This is important because centralized databases create a very obvious target.
If a company stores millions of users' sensitive information in one place, compromising that database can potentially expose an enormous amount of information.
With secret sharing, the system can distribute pieces of protected information across different nodes. The individual pieces are not useful on their own, and the original information can be reconstructed when an authorized application needs it.
So instead of thinking:
"My entire secret lives inside one database."
Think:
"The system has distributed protected pieces that can be used through controlled computation."
That is the role nilDB plays in the larger Nillion architecture.
nilCC: The Part That Actually Computes
Storage alone doesn't solve the problem.
You could encrypt everything on earth, but if you have to completely decrypt it every time you want to use it, you've only solved part of the privacy equation.
This is where nilCC, Nillion's confidential compute layer, becomes important.
nilCC allows developers to run general-purpose workloads inside Trusted Execution Environments, or TEEs. These environments are designed to isolate sensitive workloads and provide cryptographic attestation that the expected software is running inside the protected environment.
For a developer, the idea is surprisingly practical.
A workload can be packaged as a Docker application, deployed to a nilCC node, and executed inside a protected environment. The developer then receives the result without needing to expose the sensitive inputs to ordinary infrastructure.
This matters because it moves privacy closer to the computation itself.
Instead of protecting data only when it is sitting still, the system is designed to protect it while useful work is being performed on it.
That is a much harder problem.
And it is also much more useful.
Then There Is nilAI
This is where Nillion's idea becomes much easier for normal people to understand.
nilAI is Nillion's private AI layer, built on top of nilCC. It allows developers to run compatible AI models inside confidential compute environments so that sensitive prompts and data can be processed without being exposed in unencrypted form to the infrastructure handling the workload.
Imagine you have a folder containing ten years of personal documents.
You want an AI to analyze them.
You might ask:
"What are the biggest financial mistakes I've made over the last five years?"
A normal AI service needs access to the information required to answer that question.
A privacy-focused AI system should ideally be able to use that information without turning your entire private archive into readable data sitting on someone else's infrastructure.
That's the type of application Nillion is trying to enable.
And the implications become much larger when we stop thinking about AI as a chatbot.
The Real Opportunity Is AI Agents
The next generation of AI is unlikely to be limited to answering questions.
AI agents are being designed to act on behalf of users. They may eventually manage workflows, interact with applications, analyze information, make recommendations, and execute tasks based on a user's instructions.
But an agent that can actually do things for you needs context.
A financial agent might need to understand your spending.
A work agent might need access to company documents.
A personal assistant might need your schedule and preferences.
A healthcare application might need sensitive medical information.
The problem is obvious: the more capable the agent becomes, the more sensitive the information it needs.
This creates what could become one of the biggest infrastructure problems of the AI era.
We want AI to know enough to be useful.
We don't want every system involved in running that AI to know everything about us.
That's where private computation becomes important.
Nillion is essentially betting that privacy will become an infrastructure requirement for AI, rather than a feature added to an application later.
And It Goes Beyond AI
AI is probably the easiest use case to understand, but Nillion's Blind Computer is not designed exclusively for AI.
The same basic problem exists anywhere organizations need to perform useful computation on sensitive information.
Healthcare is a strong example. Hospitals, researchers and pharmaceutical companies have access to enormous datasets, but medical information is among the most sensitive categories of data that exists.
Nillion highlights private healthcare research as one potential use case for its infrastructure, where organizations could collaborate on sensitive datasets without simply pooling raw patient information into one exposed database.
Finance presents another obvious application. Institutions often need to coordinate around information that cannot simply be made public. Private computation could allow parties to perform calculations or coordinate strategies while reducing unnecessary exposure of their underlying data.
Identity is another interesting area. In a traditional system, proving something about yourself often means revealing far more information than is actually necessary. Privacy-preserving infrastructure could eventually allow applications to verify specific facts without requiring users to expose their complete identity.
And then there is Web3.
Public blockchains are powerful precisely because transactions and state can be verified publicly. But not every input into an application needs to be public.
Private credentials, confidential strategies, sensitive business logic, private identity and AI agents could all benefit from infrastructure capable of interacting with decentralized systems without making every piece of underlying information transparent.
Nillion is positioning its Blind Computer for precisely these kinds of applications.
The Nillion Stack
All of this can sound complicated when the technologies are discussed separately.
The easiest way to understand the architecture is to think of Nillion as a stack.
nilDB handles private data storage.
nilCC handles confidential computation.
nilAI brings private AI workloads into that environment.
Together, they form the core of Nillion's Blind Computer architecture.
The important thing is that these components aren't isolated ideas.
Private storage is useful because applications need somewhere to keep sensitive information.
Private computation is useful because applications need to actually do something with that information.
Private AI is useful because increasingly, the thing doing that computation will be an AI model.
The stack connects those pieces.
There is also another important part of Nillion's architecture: verification.
Because once computation becomes private, another question appears.
How do you know the computation was actually performed correctly?
That's where Nillion's verification infrastructure, including Blacklight, becomes relevant.
Privacy alone isn't enough.
Private computation needs a way to be trusted without simply asking users to trust the operator.
So What Does Nillion Actually Do for You?
This is probably the most important question.
If you're not a developer, why should you care about Nillion?
Because you are already generating enormous amounts of data.
Every day you create:
Financial informationSearch historyMessagesDocumentsLocation informationHealth informationWork dataPersonal preferencesAI conversations
And AI is going to make that data even more valuable.
The more AI understands about you, the more useful it can become.
But that creates a fundamental choice.
Do we make AI powerful by giving centralized systems access to everything?
Or can we build AI systems that can work with sensitive information while keeping that information protected?
Nillion is betting on the second option.
That is why its technology matters beyond crypto.
The consumer doesn't necessarily need to interact with Nillion directly.
Instead, the user could interact with an application built on Nillion's infrastructure.
The privacy layer works underneath.
And ideally, the user gets the benefit without having to understand the underlying cryptography.
Nillion Isn't the App. It's the Infrastructure Underneath the App.
This distinction is worth remembering.
Nillion isn't trying to become the next consumer social network.
You probably won't wake up tomorrow and open "Nillion" to check your messages.
Instead, the long-term vision is that developers build applications on top of Nillion.
You use the application.
The application uses Nillion.
Nillion handles parts of the private storage, computation or AI workload underneath.
You may never even know it is there.
That's actually what good infrastructure looks like.
Nobody thinks about the servers running their favorite application.
Nobody thinks about the database behind the website.
And eventually, users may not think about the privacy infrastructure protecting their data either.
They'll simply use an application that can do something useful with sensitive information without requiring them to expose everything.
The Bigger Bet
Nillion is ultimately making a bet about where computing is going.
The first era of the internet was about making information accessible.
The next era was about making applications programmable and decentralized.
The next era may be about making applications intelligent.
But intelligence requires data.
A lot of data.
And much of that data will be extremely sensitive.
If AI agents are going to become personal, they need personal context. If healthcare AI is going to become useful, it needs medical context. If financial AI is going to manage money, it needs financial context. If enterprise AI is going to work with proprietary information, it needs access to proprietary information.
The obvious solution is to simply give AI everything.
The better solution would be to make the data usable without making the data itself unnecessarily exposed.
That's the problem Nillion is trying to solve.
Its Blind Computer combines private storage, confidential computation and private AI into a single infrastructure stack, with verification adding another layer of trust around private workloads.
The technology is complex.
The idea isn't.
Nillion wants to make it possible for software to work with your most sensitive information without requiring the infrastructure behind that software to see everything.
And if AI really does become the interface through which we interact with much of the digital world, that could become one of the most important infrastructure problems to solve.
Because the future isn't just going to need smarter computers. It is going to need computers that can be trusted with the things we cannot afford to expose.
$NIL
{spot}(NILUSDT)
What Nillion Actually Does
Privacy has always had a problem on the internet: the moment you want software to do something useful with your data, you usually have to give that software access to the data itself.
That trade-off was manageable when most software was simple. You searched for something, opened a website, sent an email, or uploaded a document. But the internet is changing rapidly. AI systems are becoming more personalized, applications are becoming more autonomous, and AI agents are expected to work with increasingly sensitive information. The more useful these systems become, the more context they need. And much of that context is private.
Your financial information is private. Your medical records are private. Your work documents are private. Your personal conversations are private. Even something as simple as your preferences, browsing history, or instructions to an AI can reveal a surprising amount about you.
So we have a problem.
We want software to use more of our data, but we don't necessarily want the software infrastructure processing that data to see everything inside it.
This is where Nillion comes in.
Nillion is building what it calls a Blind Computer, a decentralized network designed to store and process sensitive information while keeping that information protected from application backends and the operators running the underlying infrastructure. Its central idea is straightforward: make data usable without requiring the raw data to be exposed.
That sounds simple.
The technology underneath it is not.
The Problem Nillion Is Trying to Solve
Most modern applications follow a familiar model. You provide some information, the application sends it to a backend, the backend processes it, and you receive a result.
For example, imagine uploading a private document to an AI application and asking:
"Summarize this document and tell me what I need to do next."
The AI needs to process the document to answer your question. Traditionally, that means the service needs access to the document in a form it can actually read and compute over.
That creates a trust relationship.
You are effectively saying:
"Here is my sensitive information. I trust your infrastructure to process it correctly, protect it from unauthorized access, and not expose it."
Encryption helps protect information while it is being transmitted or sitting in storage. But historically, there has been a difficult point in the middle: computation.
At some point, the system has to do something with the data.
The traditional pattern is essentially:
Encrypt → Decrypt → Compute → Encrypt again.
The problem is that during the computation stage, the information may exist in a form that the infrastructure can potentially access.
Nillion is trying to change that model.
Its Blind Computer combines privacy-enhancing technologies such as secure multi-party computation, homomorphic encryption and trusted execution environments to allow sensitive information to be stored and processed while reducing the need to expose the underlying data to infrastructure operators.
The philosophical shift is important.
Instead of saying:
"Trust us with your data."
The goal becomes:
"Trust the technology protecting the computation."
Think of Nillion as a Privacy Layer for Computation
One of the easiest ways to misunderstand Nillion is to think of it as simply another blockchain.
That's not really the interesting part.
Blockchains are exceptionally good at creating shared, transparent state between parties that do not necessarily trust each other. But transparency is not always desirable. There are plenty of situations where you want the result of a computation to be useful without exposing all of the information that produced that result.
Nillion is targeting that other side of the equation.
Blockchains made it possible to coordinate without trusting a central intermediary. Nillion is trying to make computation possible without exposing sensitive information to the infrastructure performing it.
That makes the concept particularly interesting in a world where AI is becoming more important.
An AI model is only as useful as the context it receives.
Give an AI generic information and you get a generic assistant.
Give it your actual documents, preferences, financial information, work history, personal goals and other context, and it can potentially become much more useful.
But that creates an uncomfortable question:
How much of your life are you willing to hand over to an AI provider?
Nillion's answer is to build infrastructure where sensitive information can remain protected while still being used by applications.
That is the bigger idea behind the Blind Computer.
Enter Nillion
This is where Nillion's core proposition becomes clearer.
The goal isn't to stop applications from using sensitive information. It is to change how that information is made available to computation.
Instead of treating privacy as a feature added at the end, Nillion wants privacy to exist inside the computing infrastructure itself.
The result Nillion is aiming for can be summarized very simply:
Protect the input.
Compute privately.
Reveal only the useful result.
That sounds straightforward, but achieving it requires several different technologies and infrastructure components working together.
How Does Nillion Actually Do It?
Nillion doesn't rely on one single privacy technology. Its current Blind Computer stack is divided into different modules that handle different parts of the problem.
Three of the most important are nilDB, nilCC and nilAI.
At a high level, the process looks something like this:
Your sensitive information → protected infrastructure → private computation → useful result
The important part is that the application doesn't need to treat the underlying raw information as ordinary, openly accessible server data throughout the process.
That is what makes Nillion different from simply putting another database behind an application.
nilDB: Private Storage
nilDB is Nillion's private storage layer. Data can be encrypted and split into secret shares before those shares are distributed across multiple nodes. The idea is that an individual node should not be able to simply look at the complete original information sitting inside the system.
This is important because centralized databases create a very obvious target.
If a company stores millions of users' sensitive information in one place, compromising that database can potentially expose an enormous amount of information.
With secret sharing, the system can distribute pieces of protected information across different nodes. The individual pieces are not useful on their own, and the original information can be reconstructed when an authorized application needs it.
So instead of thinking:
"My entire secret lives inside one database."
Think:
"The system has distributed protected pieces that can be used through controlled computation."
That is the role nilDB plays in the larger Nillion architecture.
nilCC: The Part That Actually Computes
Storage alone doesn't solve the problem.
You could encrypt everything on earth, but if you have to completely decrypt it every time you want to use it, you've only solved part of the privacy equation.
This is where nilCC, Nillion's confidential compute layer, becomes important.
nilCC allows developers to run general-purpose workloads inside Trusted Execution Environments, or TEEs. These environments are designed to isolate sensitive workloads and provide cryptographic attestation that the expected software is running inside the protected environment.
For a developer, the idea is surprisingly practical.
A workload can be packaged as a Docker application, deployed to a nilCC node, and executed inside a protected environment. The developer then receives the result without needing to expose the sensitive inputs to ordinary infrastructure.
This matters because it moves privacy closer to the computation itself.
Instead of protecting data only when it is sitting still, the system is designed to protect it while useful work is being performed on it.
That is a much harder problem.
And it is also much more useful.
Then There Is nilAI
This is where Nillion's idea becomes much easier for normal people to understand.
nilAI is Nillion's private AI layer, built on top of nilCC. It allows developers to run compatible AI models inside confidential compute environments so that sensitive prompts and data can be processed without being exposed in unencrypted form to the infrastructure handling the workload.
Imagine you have a folder containing ten years of personal documents.
You want an AI to analyze them.
You might ask:
"What are the biggest financial mistakes I've made over the last five years?"
A normal AI service needs access to the information required to answer that question.
A privacy-focused AI system should ideally be able to use that information without turning your entire private archive into readable data sitting on someone else's infrastructure.
That's the type of application Nillion is trying to enable.
And the implications become much larger when we stop thinking about AI as a chatbot.
The Real Opportunity Is AI Agents
The next generation of AI is unlikely to be limited to answering questions.
AI agents are being designed to act on behalf of users. They may eventually manage workflows, interact with applications, analyze information, make recommendations, and execute tasks based on a user's instructions.
But an agent that can actually do things for you needs context.
A financial agent might need to understand your spending.
A work agent might need access to company documents.
A personal assistant might need your schedule and preferences.
A healthcare application might need sensitive medical information.
The problem is obvious: the more capable the agent becomes, the more sensitive the information it needs.
This creates what could become one of the biggest infrastructure problems of the AI era.
We want AI to know enough to be useful.
We don't want every system involved in running that AI to know everything about us.
That's where private computation becomes important.
Nillion is essentially betting that privacy will become an infrastructure requirement for AI, rather than a feature added to an application later.
And It Goes Beyond AI
AI is probably the easiest use case to understand, but Nillion's Blind Computer is not designed exclusively for AI.
The same basic problem exists anywhere organizations need to perform useful computation on sensitive information.
Healthcare is a strong example. Hospitals, researchers and pharmaceutical companies have access to enormous datasets, but medical information is among the most sensitive categories of data that exists.
Nillion highlights private healthcare research as one potential use case for its infrastructure, where organizations could collaborate on sensitive datasets without simply pooling raw patient information into one exposed database.
Finance presents another obvious application. Institutions often need to coordinate around information that cannot simply be made public. Private computation could allow parties to perform calculations or coordinate strategies while reducing unnecessary exposure of their underlying data.
Identity is another interesting area. In a traditional system, proving something about yourself often means revealing far more information than is actually necessary. Privacy-preserving infrastructure could eventually allow applications to verify specific facts without requiring users to expose their complete identity.
And then there is Web3.
Public blockchains are powerful precisely because transactions and state can be verified publicly. But not every input into an application needs to be public.
Private credentials, confidential strategies, sensitive business logic, private identity and AI agents could all benefit from infrastructure capable of interacting with decentralized systems without making every piece of underlying information transparent.
Nillion is positioning its Blind Computer for precisely these kinds of applications.
The Nillion Stack
All of this can sound complicated when the technologies are discussed separately.
The easiest way to understand the architecture is to think of Nillion as a stack.
nilDB handles private data storage.
nilCC handles confidential computation.
nilAI brings private AI workloads into that environment.
Together, they form the core of Nillion's Blind Computer architecture.
The important thing is that these components aren't isolated ideas.
Private storage is useful because applications need somewhere to keep sensitive information.
Private computation is useful because applications need to actually do something with that information.
Private AI is useful because increasingly, the thing doing that computation will be an AI model.
The stack connects those pieces.
There is also another important part of Nillion's architecture: verification.
Because once computation becomes private, another question appears.
How do you know the computation was actually performed correctly?
That's where Nillion's verification infrastructure, including Blacklight, becomes relevant.
Privacy alone isn't enough.
Private computation needs a way to be trusted without simply asking users to trust the operator.
So What Does Nillion Actually Do for You?
This is probably the most important question.
If you're not a developer, why should you care about Nillion?
Because you are already generating enormous amounts of data.
Every day you create:
Financial informationSearch historyMessagesDocumentsLocation informationHealth informationWork dataPersonal preferencesAI conversations
And AI is going to make that data even more valuable.
The more AI understands about you, the more useful it can become.
But that creates a fundamental choice.
Do we make AI powerful by giving centralized systems access to everything?
Or can we build AI systems that can work with sensitive information while keeping that information protected?
Nillion is betting on the second option.
That is why its technology matters beyond crypto.
The consumer doesn't necessarily need to interact with Nillion directly.
Instead, the user could interact with an application built on Nillion's infrastructure.
The privacy layer works underneath.
And ideally, the user gets the benefit without having to understand the underlying cryptography.
Nillion Isn't the App. It's the Infrastructure Underneath the App.
This distinction is worth remembering.
Nillion isn't trying to become the next consumer social network.
You probably won't wake up tomorrow and open "Nillion" to check your messages.
Instead, the long-term vision is that developers build applications on top of Nillion.
You use the application.
The application uses Nillion.
Nillion handles parts of the private storage, computation or AI workload underneath.
You may never even know it is there.
That's actually what good infrastructure looks like.
Nobody thinks about the servers running their favorite application.
Nobody thinks about the database behind the website.
And eventually, users may not think about the privacy infrastructure protecting their data either.
They'll simply use an application that can do something useful with sensitive information without requiring them to expose everything.
The Bigger Bet
Nillion is ultimately making a bet about where computing is going.
The first era of the internet was about making information accessible.
The next era was about making applications programmable and decentralized.
The next era may be about making applications intelligent.
But intelligence requires data.
A lot of data.
And much of that data will be extremely sensitive.
If AI agents are going to become personal, they need personal context. If healthcare AI is going to become useful, it needs medical context. If financial AI is going to manage money, it needs financial context. If enterprise AI is going to work with proprietary information, it needs access to proprietary information.
The obvious solution is to simply give AI everything.
The better solution would be to make the data usable without making the data itself unnecessarily exposed.
That's the problem Nillion is trying to solve.
Its Blind Computer combines private storage, confidential computation and private AI into a single infrastructure stack, with verification adding another layer of trust around private workloads.
The technology is complex.
The idea isn't.
Nillion wants to make it possible for software to work with your most sensitive information without requiring the infrastructure behind that software to see everything.
And if AI really does become the interface through which we interact with much of the digital world, that could become one of the most important infrastructure problems to solve.
Because the future isn't just going to need smarter computers. It is going to need computers that can be trusted with the things we cannot afford to expose.
$NIL
3
602
Backpack-issued tokenized stocks on Solana have surpassed 300,000 holders.
Backpack-issued tokenized stocks on Solana have surpassed 300,000 holders.
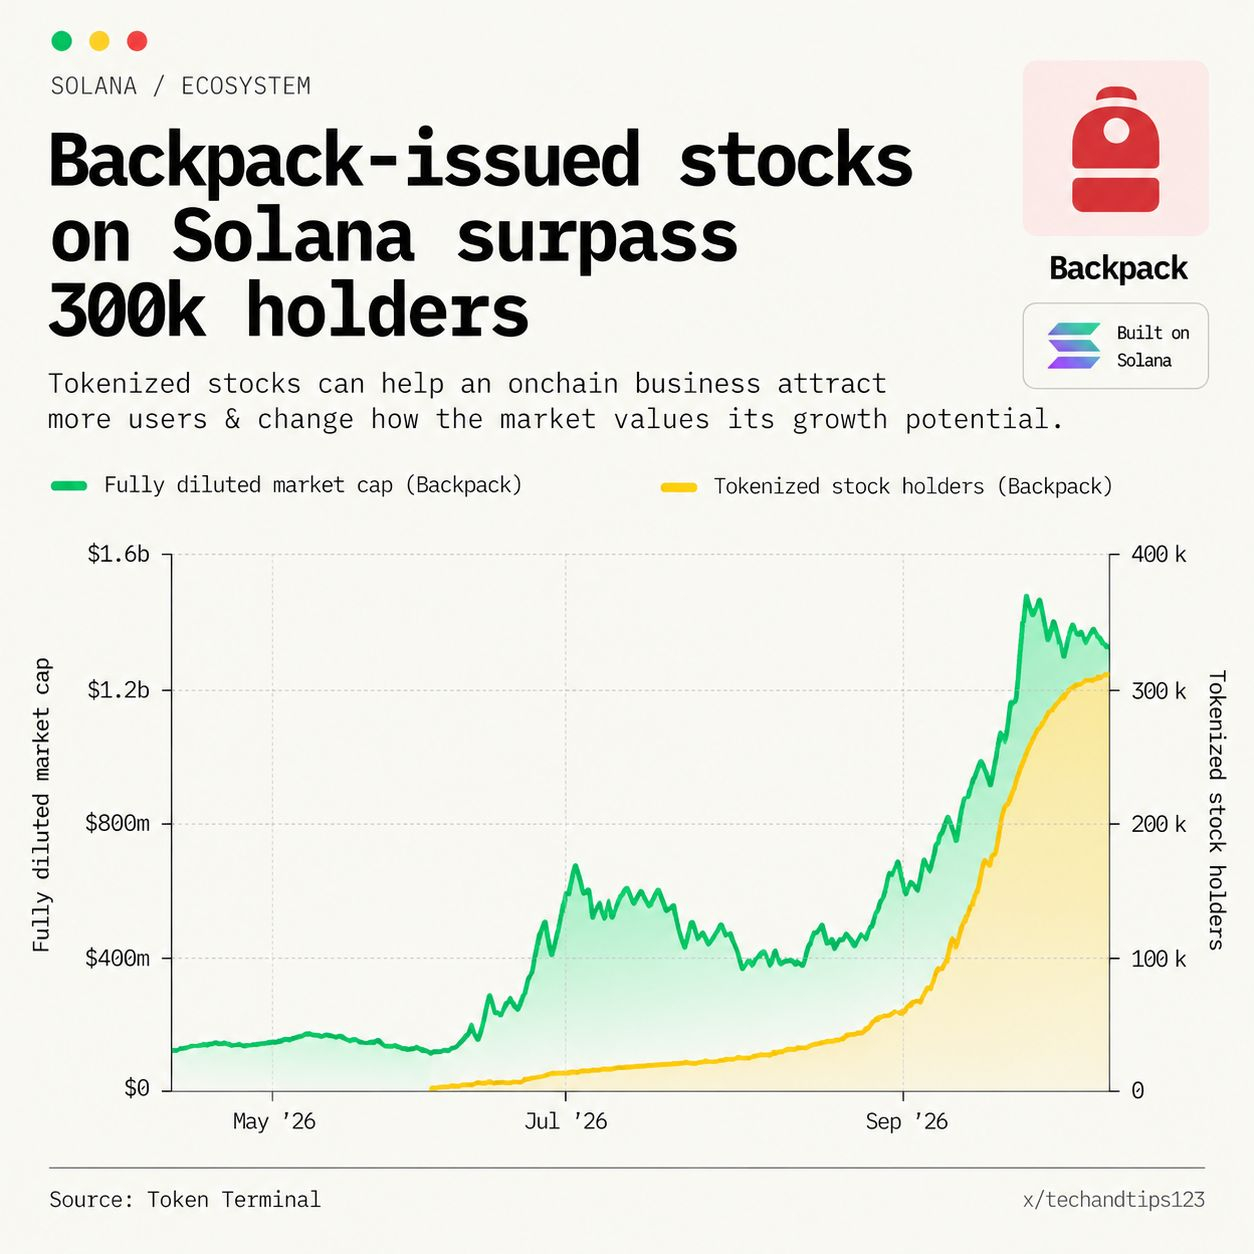
2
525
Vérifié
☀️ 6 𝐓𝐡𝐢𝐧𝐠𝐬 𝐘𝐨𝐮 𝐌𝐢𝐬𝐬𝐞𝐝 𝐨𝐧 𝐁𝐢𝐧𝐚𝐧𝐜𝐞 𝐢𝐧 𝐭𝐡𝐞 𝐋𝐚𝐬𝐭 24𝐇 ☀️
-
• Binance launched Binance Intelligence, an AI product stack built into the app. Binance AI is free and rolling out progressively, so check your app for access. Availability depends on your region.
• Binance AI Pro turns plain-language ideas into automated strategies that run 24/7. It arrives in the second half of October on a freemium model. Test any AI strategy with small size first.
• Brazilian users must give transfer details for international deposits and withdrawals from Nov 1. Transfers may be delayed or returned if info is missing.
• $HYPE 's core contributor unlock is due today, Oct 6. Check your leverage now.
• The $BTC and ETH Options Trading Cup ends tomorrow, Oct 7. Don't trade options just for the prize pool.
• Withdrawals for ACX, HFT, PIVX, PYR, VANRY and VIC close Oct 17. Move your coins now.
1
720
𝐁𝐞𝐬𝐭 𝕓𝕊𝕋𝕆ℂ𝕂𝕊 𝐁𝐮𝐲𝐢𝐧𝐠 𝐎𝐩𝐩𝐨𝐫𝐭𝐮𝐧𝐢𝐭𝐢𝐞𝐬 𝐢𝐧 𝐁𝐢𝐧𝐚𝐧𝐜𝐞 : 6th October 2026 $SPCXB $NVDAB
𝐁𝐞𝐬𝐭 𝕓𝕊𝕋𝕆ℂ𝕂𝕊 𝐁𝐮𝐲𝐢𝐧𝐠 𝐎𝐩𝐩𝐨𝐫𝐭𝐮𝐧𝐢𝐭𝐢𝐞𝐬 𝐢𝐧 𝐁𝐢𝐧𝐚𝐧𝐜𝐞 : 6th October 2026 $SPCXB $NVDAB
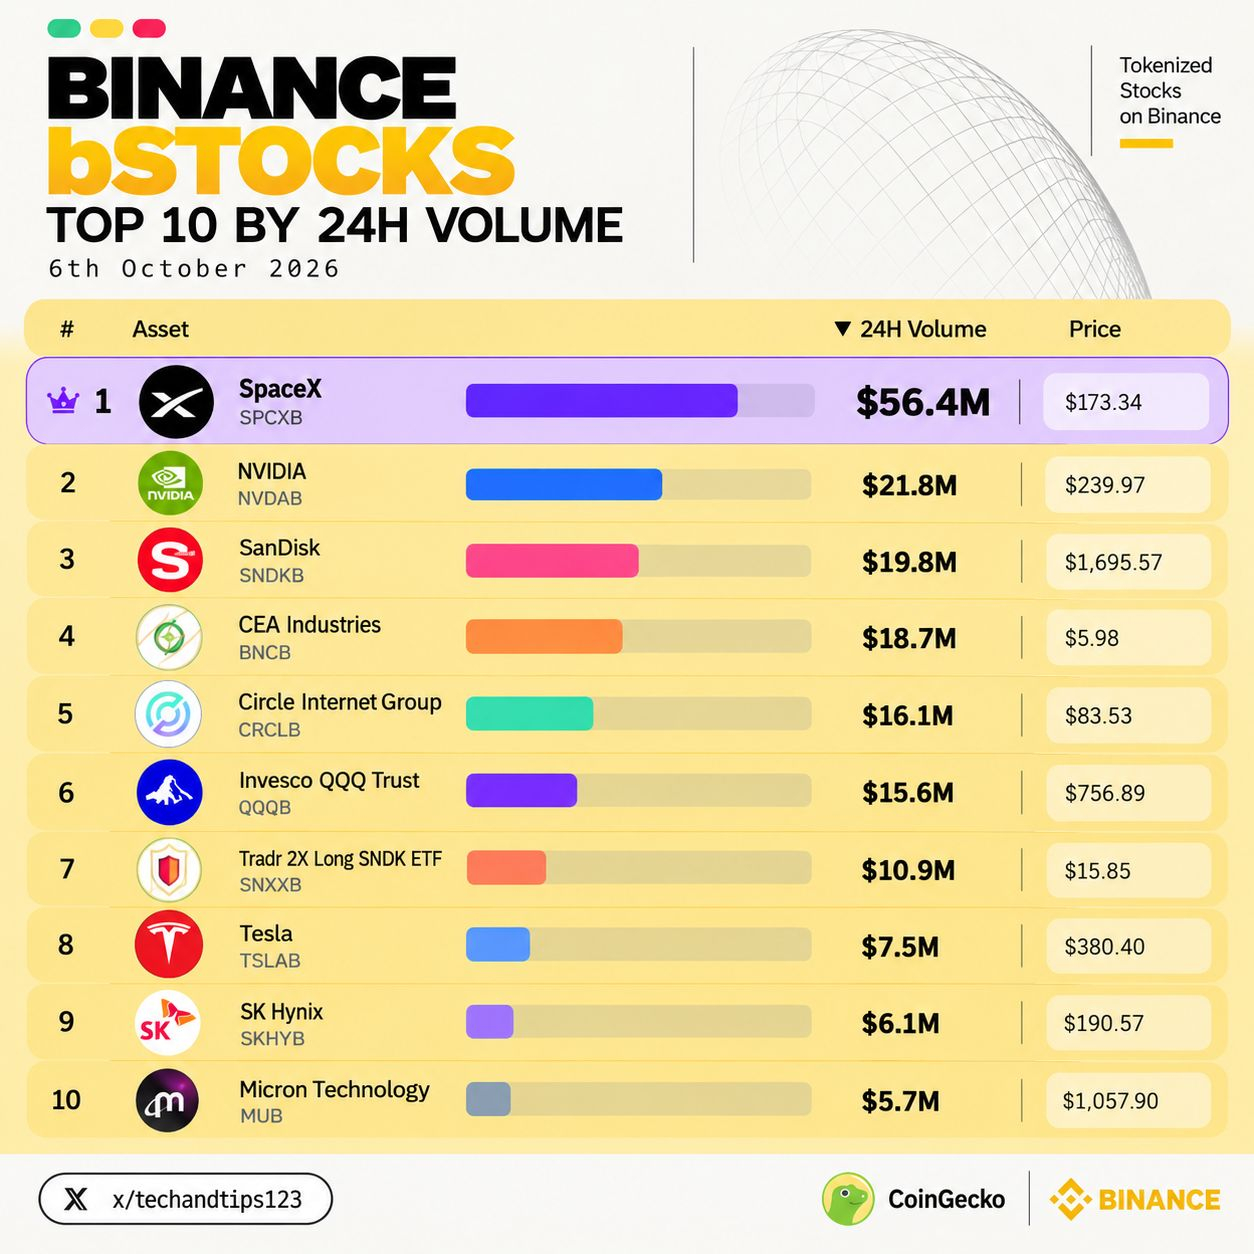
5
1.1k
𝐓𝐡𝐞𝐬𝐞 𝐂𝐨𝐢𝐧𝐬 𝐂𝐚𝐧 𝐏𝐮𝐦𝐩 𝐀𝐧𝐲𝐭𝐢𝐦𝐞 - 𝐁𝐢𝐠𝐠𝐞𝐬𝐭 𝐕𝐨𝐥𝐮𝐦𝐞 𝐆𝐚𝐢𝐧𝐞𝐫𝐬 24𝐡 $RLC $NIL $TURTLE
𝐓𝐡𝐞𝐬𝐞 𝐂𝐨𝐢𝐧𝐬 𝐂𝐚𝐧 𝐏𝐮𝐦𝐩 𝐀𝐧𝐲𝐭𝐢𝐦𝐞 - 𝐁𝐢𝐠𝐠𝐞𝐬𝐭 𝐕𝐨𝐥𝐮𝐦𝐞 𝐆𝐚𝐢𝐧𝐞𝐫𝐬 24𝐡 $RLC $NIL $TURTLE
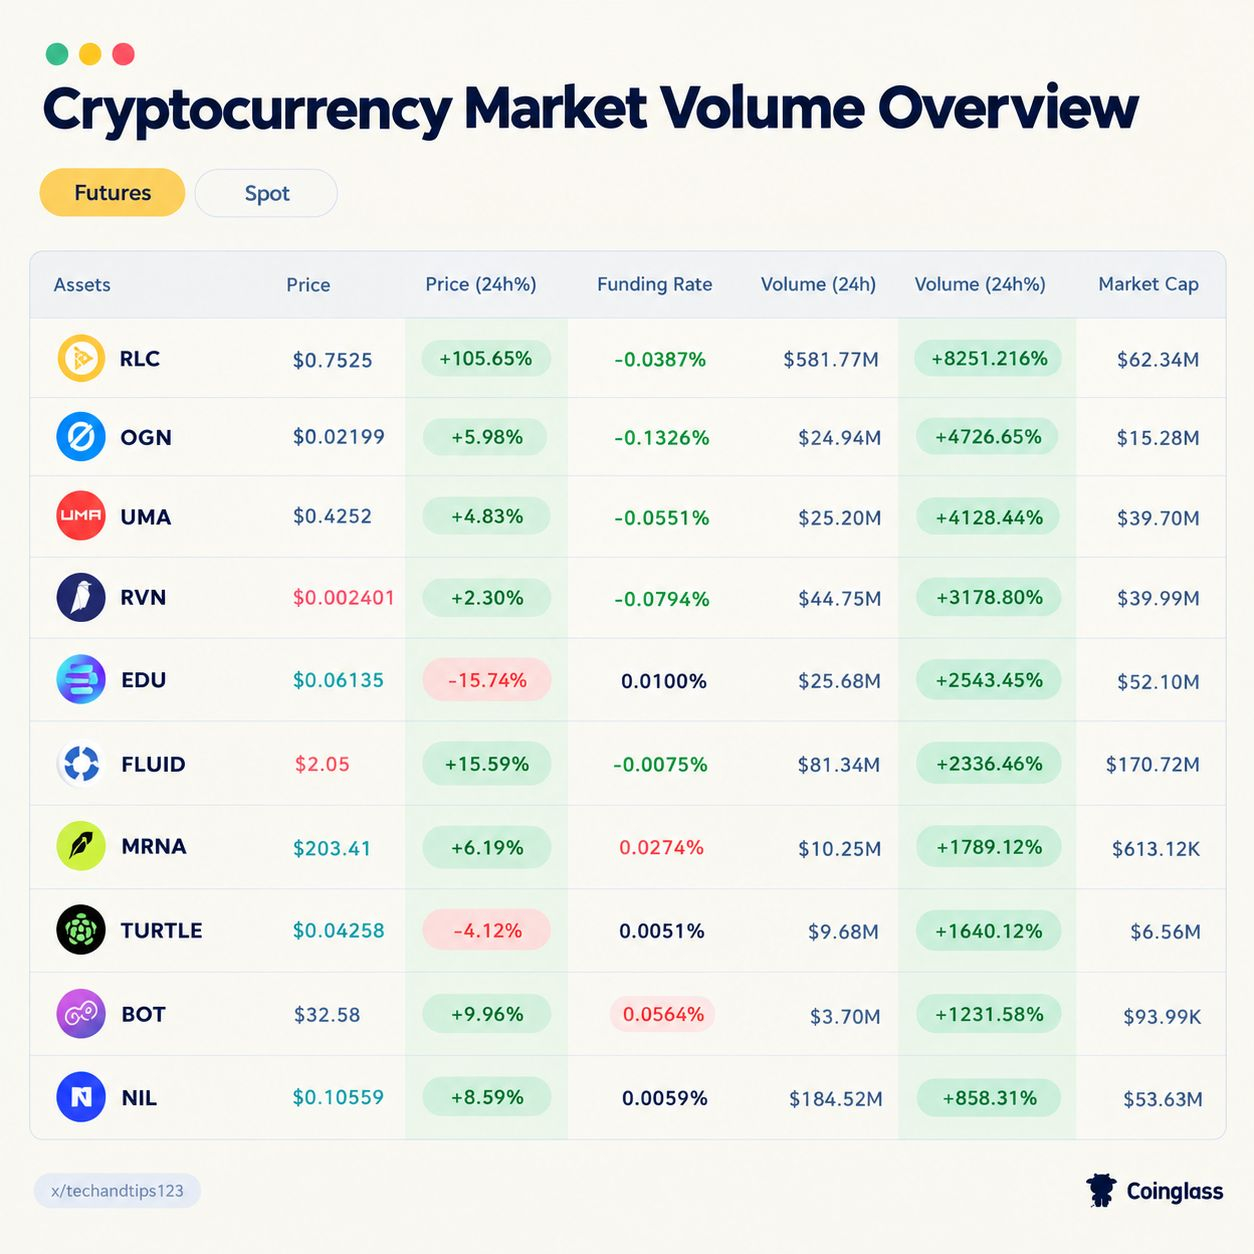
2
701
🔅𝗪𝗵𝗮𝘁 𝗗𝗶𝗱 𝗬𝗼𝘂 𝗠𝗶𝘀𝘀𝗲𝗱 𝗶𝗻 𝗖𝗿𝘆𝗽𝘁𝗼 𝗶𝗻 𝗹𝗮𝘀𝘁 24𝗛?🔅
-
• CFTC proposes federal framework for leveraged crypto exchanges
• $BTC stays below $87K as weak jobs data cuts Fed hike odds
• Bitcoin ETFs attract $241M for third straight weekly inflow
• Ethereum ETFs lose $138M as outflows continue
• BTC, $ETH , SOL and XRP increasingly treated as digital commodities
• $NVDAB Nvidia hits $5.76T market cap as AI trade lifts Nasdaq
• U.S. power shortages emerge as major AI deployment bottleneck
💡 Courtesy - Datawallet
©𝑻𝒉𝒊𝒔 𝒂𝒓𝒕𝒊𝒄𝒍𝒆 𝒊𝒔 𝒇𝒐𝒓 𝒊𝒏𝒇𝒐𝒓𝒎𝒂𝒕𝒊𝒐𝒏 𝒐𝒏𝒍𝒚 𝒂𝒏𝒅 𝒏𝒐𝒕 𝒂𝒏 𝒆𝒏𝒅𝒐𝒓𝒔𝒆𝒎𝒆𝒏𝒕 𝒐𝒇 𝒂𝒏𝒚 𝒑𝒓𝒐𝒋𝒆𝒄𝒕 𝒐𝒓 𝒆𝒏𝒕𝒊𝒕𝒚. 𝑻𝒉𝒆 𝒏𝒂𝒎𝒆𝒔 𝒎𝒆𝒏𝒕𝒊𝒐𝒏𝒆𝒅 𝒂𝒓𝒆 𝒏𝒐𝒕 𝒓𝒆𝒍𝒂𝒕𝒆𝒅 𝒕𝒐 𝒖𝒔. 𝑾𝒆 𝒂𝒓𝒆 𝒏𝒐𝒕 𝒍𝒊𝒂𝒃𝒍𝒆 𝒇𝒐𝒓 𝒂𝒏𝒚 𝒍𝒐𝒔𝒔𝒆𝒔 𝒇𝒓𝒐𝒎 𝒊𝒏𝒗𝒆𝒔𝒕𝒊𝒏𝒈 𝒃𝒂𝒔𝒆𝒅 𝒐𝒏 𝒕𝒉𝒊𝒔 𝒂𝒓𝒕𝒊𝒄𝒍𝒆. 𝑻𝒉𝒊𝒔 𝒊𝒔 𝒏𝒐𝒕 𝒇𝒊𝒏𝒂𝒏𝒄𝒊𝒂𝒍 𝒂𝒅𝒗𝒊𝒄𝒆. 𝑻𝒉𝒊𝒔 𝒅𝒊𝒔𝒄𝒍𝒂𝒊𝒎𝒆𝒓 𝒑𝒓𝒐𝒕𝒆𝒄𝒕𝒔 𝒃𝒐𝒕𝒉 𝒚𝒐𝒖 𝒂𝒏𝒅 𝒖𝒔.
🅃🄴🄲🄷🄰🄽🄳🅃🄸🄿🅂123
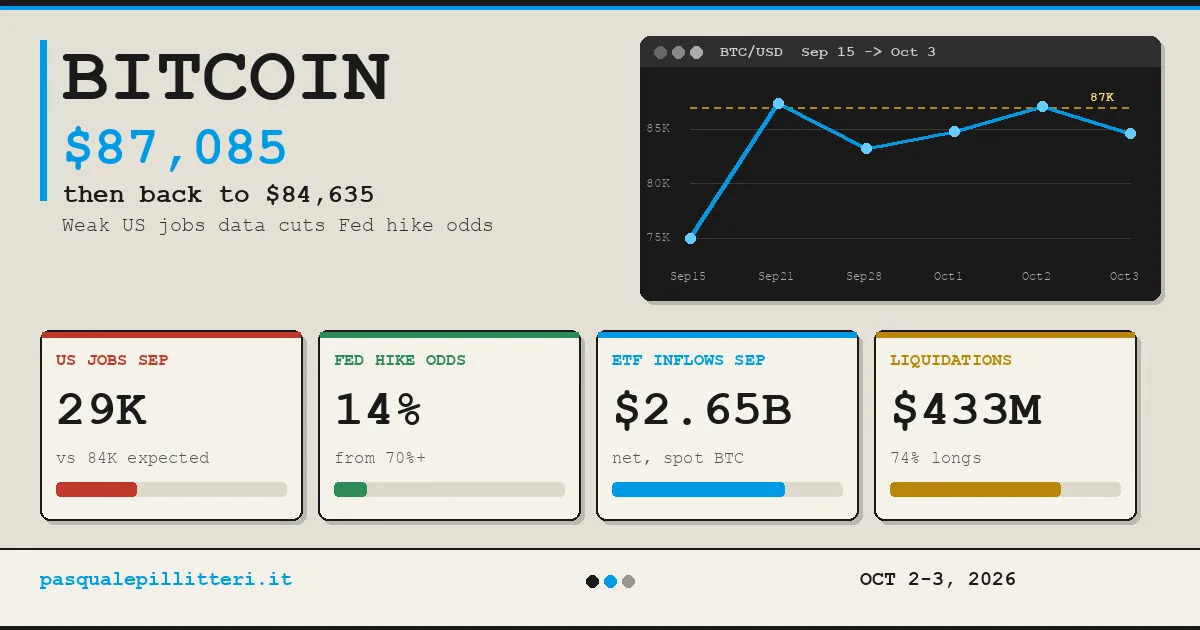
1
569
$NEAR Outperformed major AI - Based / Releted Cryptocurrencies by distant margin , it's ahead of $FET And $TAO
© Artemis
$NEAR Outperformed major AI - Based / Releted Cryptocurrencies by distant margin , it's ahead of $FET And $TAO
© Artemis
© Artemis
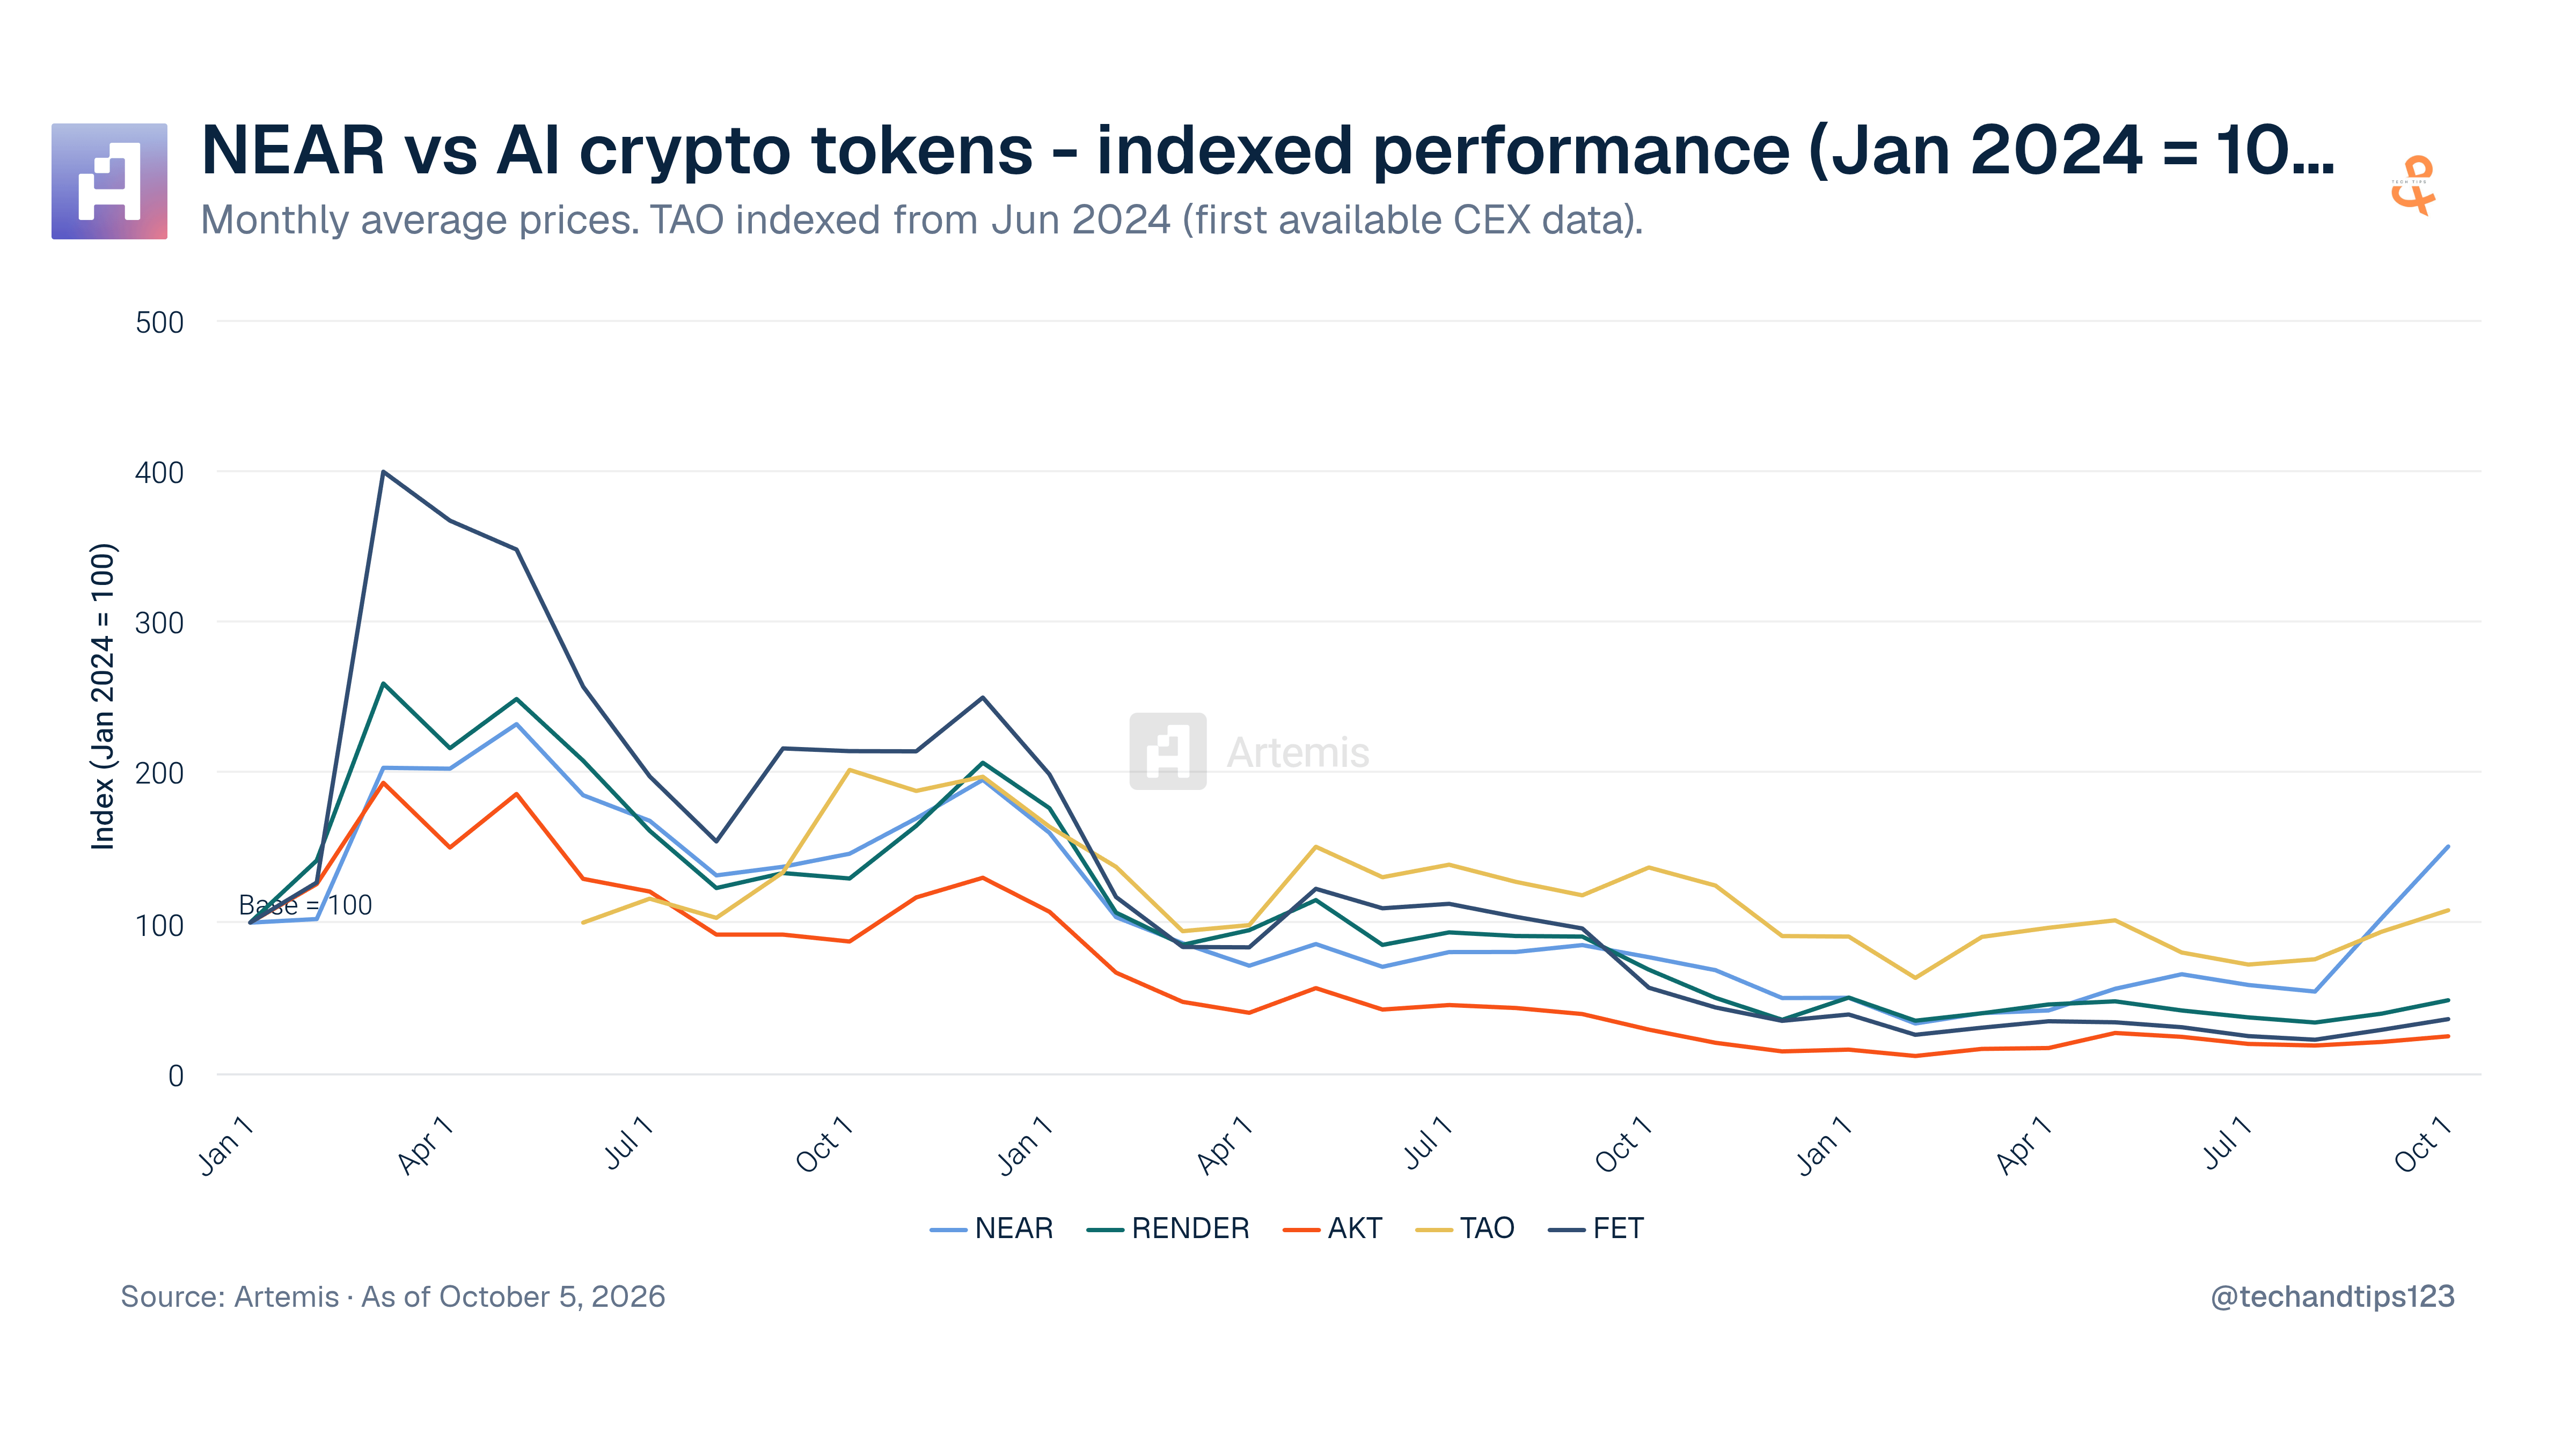
2
427
$BTC : Here's A Quick Look of Microstrategy Last 10 Bitcoin Activity
$BTC : Here's A Quick Look of Microstrategy Last 10 Bitcoin Activity
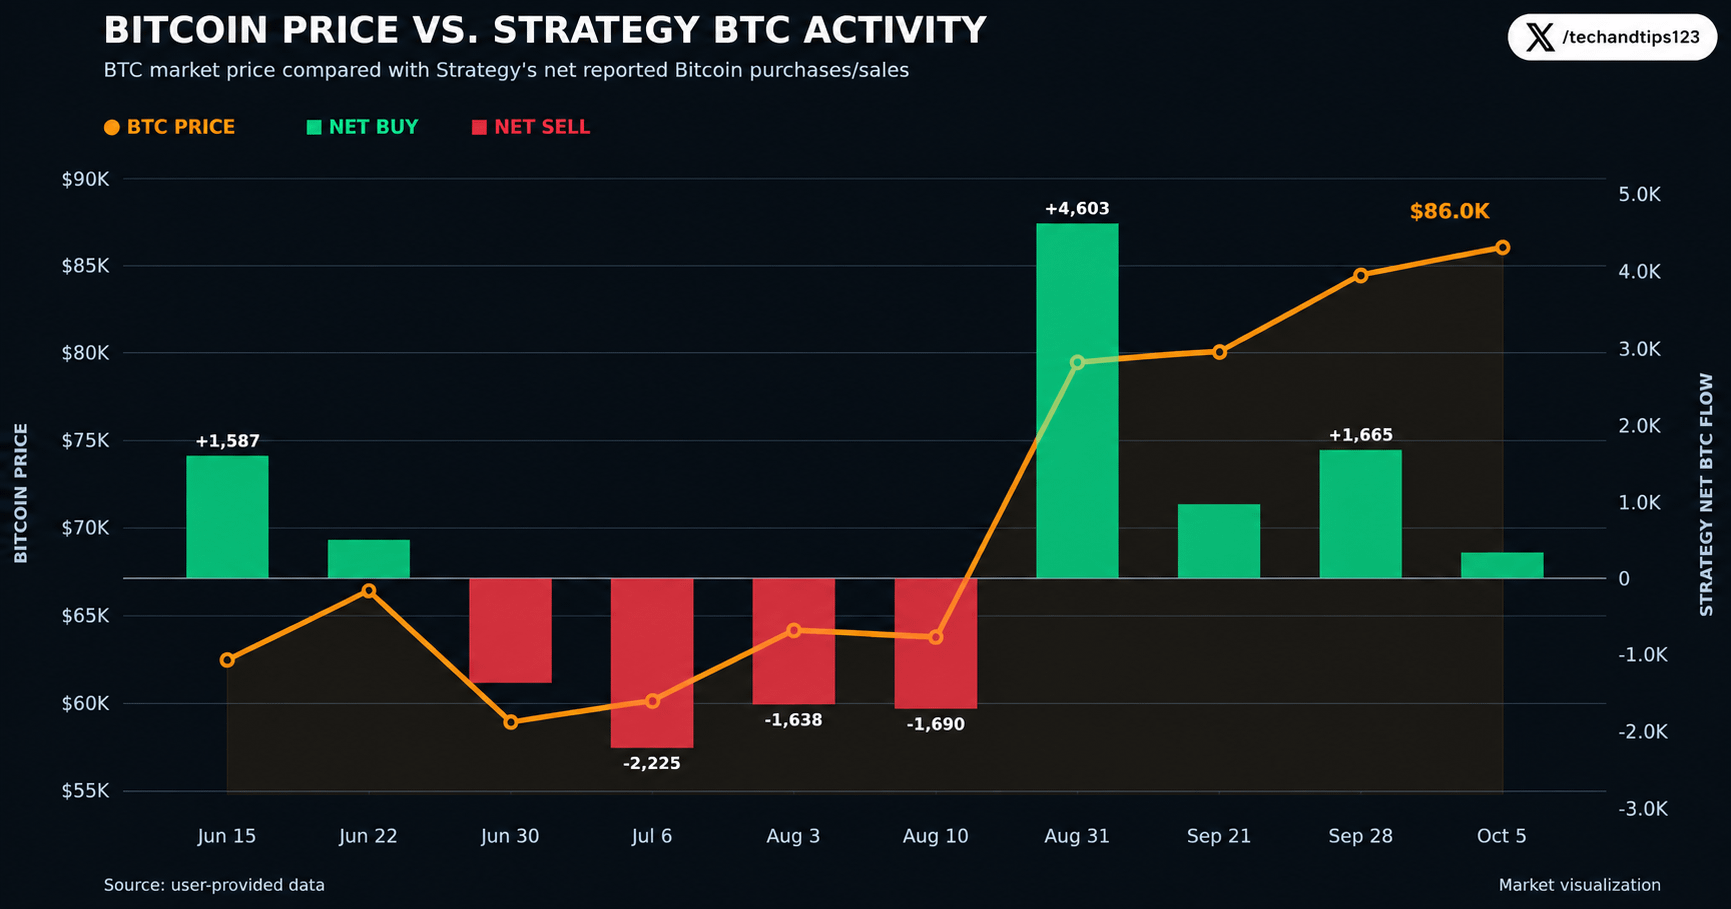
3
1
8
10.5k
Vérifié
☀️ 6 𝐓𝐡𝐢𝐧𝐠𝐬 𝐘𝐨𝐮 𝐌𝐢𝐬𝐬𝐞𝐝 𝐨𝐧 𝐁𝐢𝐧𝐚𝐧𝐜𝐞 𝐢𝐧 𝐭𝐡𝐞 𝐋𝐚𝐬𝐭 24𝐇 ☀️
-
• Binance unveils its AI-powered Binance Intelligence at 12:00 UTC on Binance Square. A 5,000 USDC giveaway is tied to the stream. Set a reminder.
• PROMPTUSDT, PUMPBTCUSDT and $1000000BOB USDT perpetuals settle automatically today at 16:30. Close positions now.
• $HYPE 's core contributor unlock is due tomorrow, Oct 6. Check your leverage tonight.
• The BTC and ETH Options Trading Cup ends Oct 7. Don't trade options just for the prize pool.
• Withdrawals for $ACX , HFT, PIVX, PYR, VANRY and VIC close Oct 17. Move your coins now.
• Binance Intelligence builds on Agent OS, its platform for connecting AI apps to Binance services. Never give any AI tool an API key with withdrawal permissions.
3
2
687
$BTC Having a New plan ; Breakout is pending ......
$BTC Having a New plan ; Breakout is pending ......
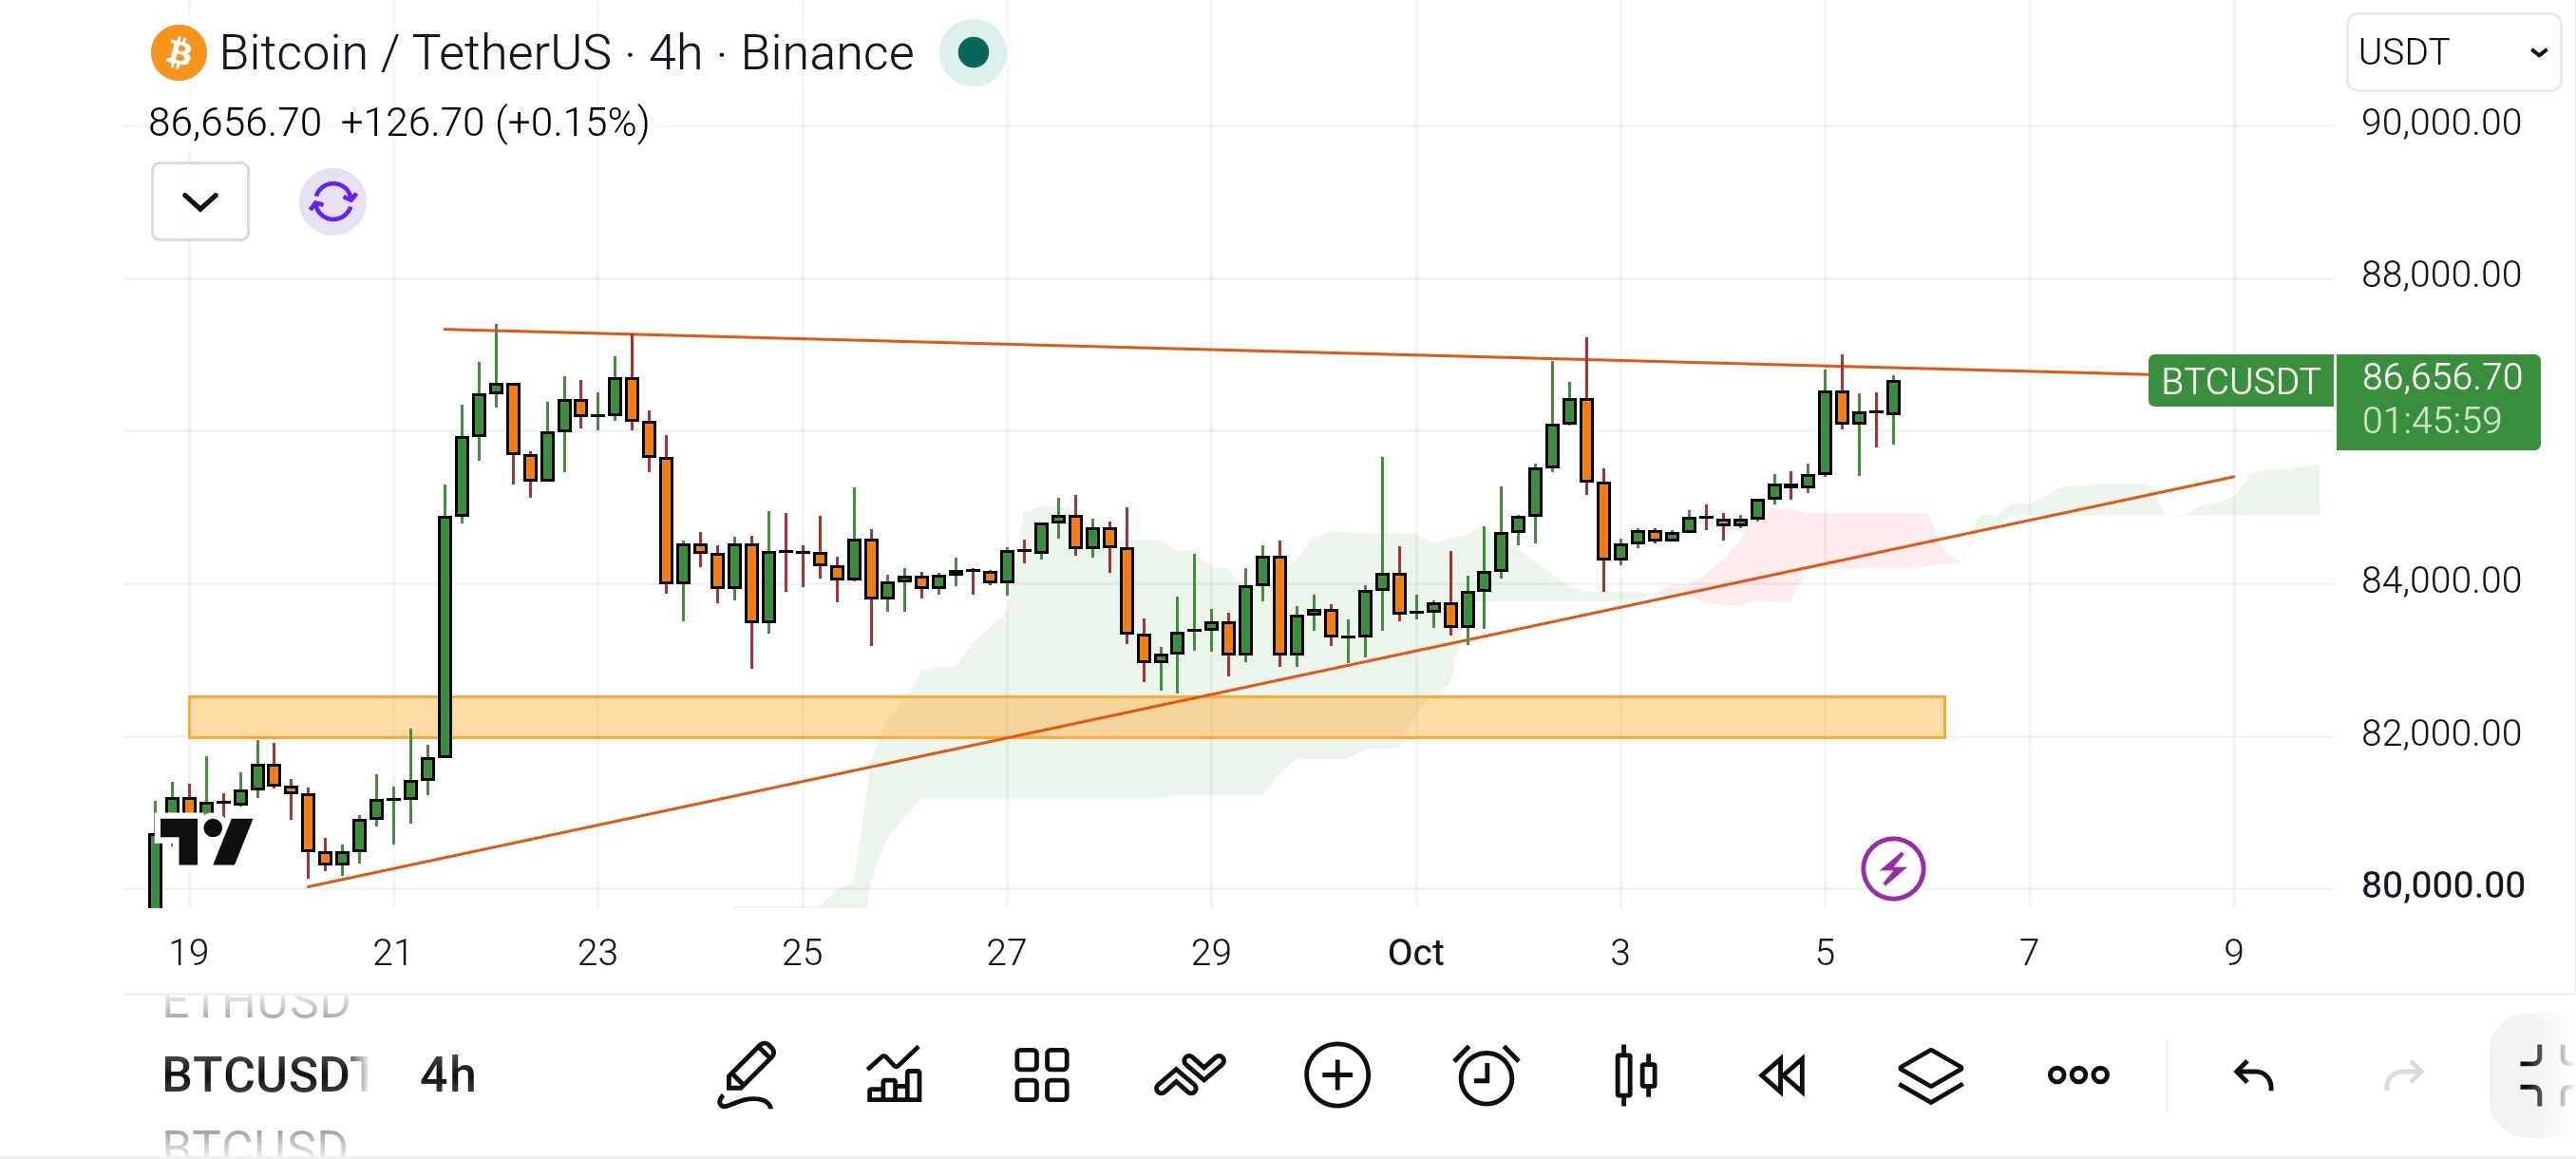
3
8
5.8k
𝐁𝐞𝐬𝐭 𝕓𝕊𝕋𝕆ℂ𝕂𝕊 𝐁𝐮𝐲𝐢𝐧𝐠 𝐎𝐩𝐩𝐨𝐫𝐭𝐮𝐧𝐢𝐭𝐢𝐞𝐬 𝐢𝐧 𝐁𝐢𝐧𝐚𝐧𝐜𝐞 : 5th October 2026 $BNCB $SPCXB $TSLAB
𝐁𝐞𝐬𝐭 𝕓𝕊𝕋𝕆ℂ𝕂𝕊 𝐁𝐮𝐲𝐢𝐧𝐠 𝐎𝐩𝐩𝐨𝐫𝐭𝐮𝐧𝐢𝐭𝐢𝐞𝐬 𝐢𝐧 𝐁𝐢𝐧𝐚𝐧𝐜𝐞 : 5th October 2026 $BNCB $SPCXB $TSLAB
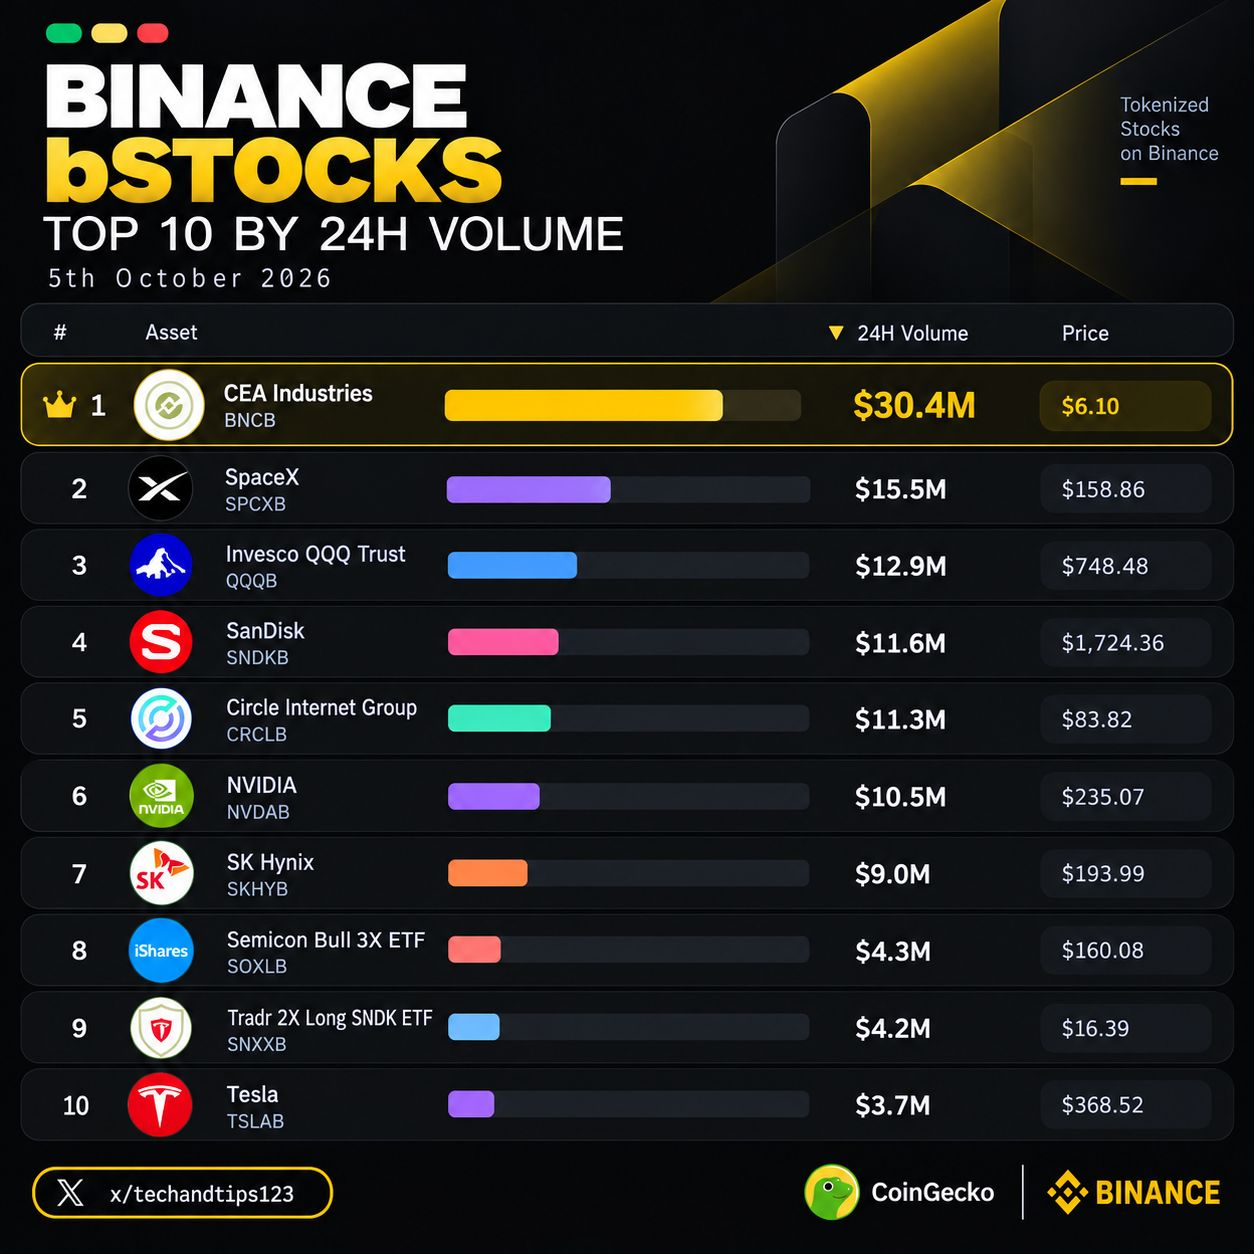
3
3.8k
𝐓𝐨𝐩 𝐓𝐫𝐞𝐧𝐝𝐢𝐧𝐠 𝐂𝐨𝐢𝐧𝐬 𝐓𝐨𝐝𝐚𝐲 : 5th October 2026 $NEAR $ONDO $STRK
𝐓𝐨𝐩 𝐓𝐫𝐞𝐧𝐝𝐢𝐧𝐠 𝐂𝐨𝐢𝐧𝐬 𝐓𝐨𝐝𝐚𝐲 : 5th October 2026 $NEAR $ONDO $STRK
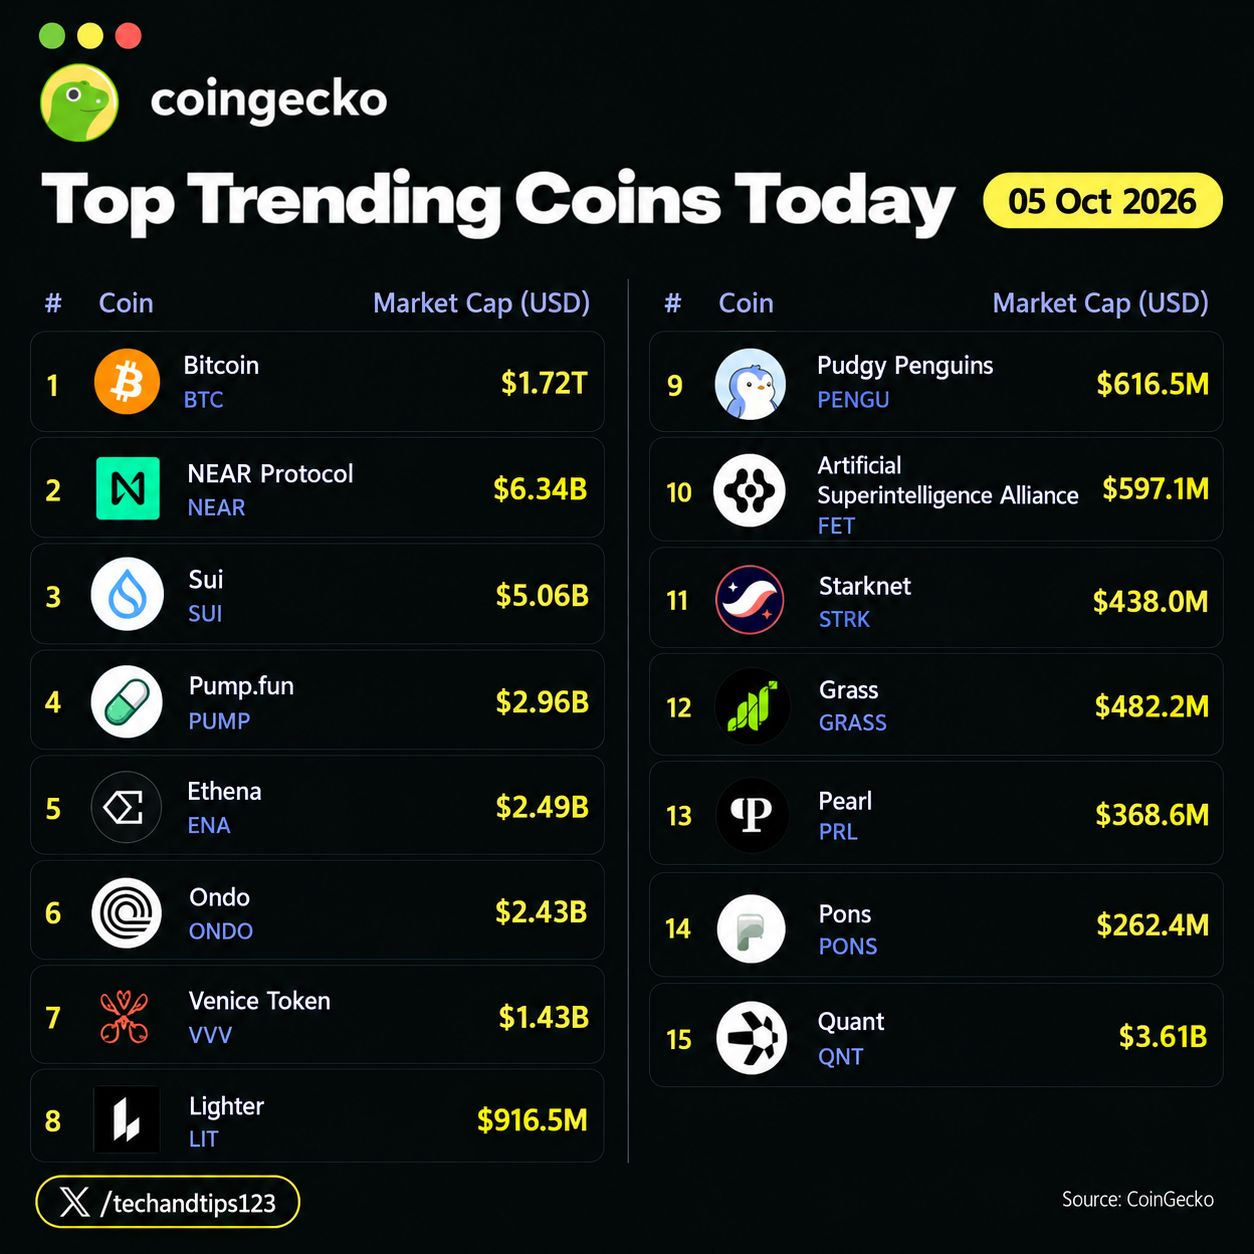
1
414
Article
The AI Labor Surge: Over 750,000 New Jobs Created Across the USThe artificial intelligence boom is reshaping the American job market at an incredible speed. For years, the main concern around technology was how many roles it might eliminate. The actual data tells a completely different story. As companies rush to build physical infrastructure and train advanced models, the demand for specialized human labor is hitting record highs.
❍ Where the New AI Jobs Are Concentrated
The expansion of artificial intelligence roles is adding hundreds of thousands of high paying positions to the economy.
AI linked roles have accounted for more than 750,000 new jobs created across the United States since 2023, according to recent estimates.This hiring wave is led by data annotators with 282,000 new positions, followed closely by data center jobs at 117,000 and AI engineers at 105,000.Together, these three specific categories account for 504,000 of the total new jobs created during this tech cycle.
❍ Premium Salaries in the Tech Sector
The financial incentive for workers entering the artificial intelligence space stands far above the traditional labor market.
AI related positions offer significantly higher compensation, boasting a median salary of roughly 180,000 dollars on LinkedIn.By comparison, the median salary across all traditional jobs sits at about 80,000 dollars.This massive wage gap is driven by the rapid expansion of physical AI infrastructure and the intense corporate demand for specialized engineering talent.
Some Random Thoughts 💬
Every major technological revolution creates an entirely new class of high value employment while forcing traditional industries to adapt. When people worry about automation taking over, they often forget that building and maintaining artificial intelligence requires massive amounts of human labor, from managing physical data centers to annotating complex datasets.
In the tech and crypto sectors, we see this exact same dynamic where cutting edge infrastructure demands specialized talent that commands top tier pay. The companies spending billions on hardware and software realize that talent is the ultimate bottleneck. If you want to future proof your career, understanding how to work alongside these new intelligence systems is quickly becoming the most valuable skill in the modern economy.
The AI Labor Surge: Over 750,000 New Jobs Created Across the US
The artificial intelligence boom is reshaping the American job market at an incredible speed. For years, the main concern around technology was how many roles it might eliminate. The actual data tells a completely different story. As companies rush to build physical infrastructure and train advanced models, the demand for specialized human labor is hitting record highs.
❍ Where the New AI Jobs Are Concentrated
The expansion of artificial intelligence roles is adding hundreds of thousands of high paying positions to the economy.
AI linked roles have accounted for more than 750,000 new jobs created across the United States since 2023, according to recent estimates.This hiring wave is led by data annotators with 282,000 new positions, followed closely by data center jobs at 117,000 and AI engineers at 105,000.Together, these three specific categories account for 504,000 of the total new jobs created during this tech cycle.
❍ Premium Salaries in the Tech Sector
The financial incentive for workers entering the artificial intelligence space stands far above the traditional labor market.
AI related positions offer significantly higher compensation, boasting a median salary of roughly 180,000 dollars on LinkedIn.By comparison, the median salary across all traditional jobs sits at about 80,000 dollars.This massive wage gap is driven by the rapid expansion of physical AI infrastructure and the intense corporate demand for specialized engineering talent.
Some Random Thoughts 💬
Every major technological revolution creates an entirely new class of high value employment while forcing traditional industries to adapt. When people worry about automation taking over, they often forget that building and maintaining artificial intelligence requires massive amounts of human labor, from managing physical data centers to annotating complex datasets.
In the tech and crypto sectors, we see this exact same dynamic where cutting edge infrastructure demands specialized talent that commands top tier pay. The companies spending billions on hardware and software realize that talent is the ultimate bottleneck. If you want to future proof your career, understanding how to work alongside these new intelligence systems is quickly becoming the most valuable skill in the modern economy.
1
310
Vérifié
🟡 𝐁𝐍𝐁 𝐂𝐡𝐚𝐢𝐧 𝐃𝐚𝐢𝐥𝐲 𝐑𝐞𝐜𝐚𝐩 | 𝐋𝐚𝐬𝐭 24𝐇 $BNB
-
• BNB Chain added $23.2M of RWA value over the latest 24H, according to RWA Foundation data citing Token Terminal. That was the second-largest daily RWA inflow among the major networks, behind Stellar's $36.4M.
• BNB Chain's RWA footprint reached $5.76B in distributed assets, with 1.98M RWA holders across 2,715 assets in the latest RWA.xyz snapshot. Stablecoin assets on BNB Chain total about $12.90B, held by 90.18M addresses.
• BNB Smart Chain recorded 16.39M daily transactions on October 3, according to BNB Chain's own DappBay dashboard. PancakeSwap accounted for 4.62M transactions and 429.95K users over seven days, remaining the largest BSC dApp by activity.
• BNB Chain DEXes processed $10.71B in 24H trading volume across 4.38M transactions, with approximately $3.86B in DEX liquidity in the October 5 snapshot. This is a fresh activity reading rather than an older cumulative-volume headline.
• The BNB Chain “Set and Earn” AI-agent campaign entered its first week, running from October 1 to November 5 with a $10,000 merchandise prize pool. The program says BNB Chain has 200,000+ registered ERC-8004 agents, and participants must hire three agents across two marketplaces and build one themselves.
3
826
$GTC Resistance Broke and it Pumped Another +20%
$GTC Resistance Broke and it Pumped Another +20%
Techandtips123
·
--
$GTC Would Like to See How this Resistance Plays Out
2
793
𝐓𝐡𝐞𝐬𝐞 𝐂𝐨𝐢𝐧𝐬 𝐂𝐚𝐧 𝐏𝐮𝐦𝐩 𝐀𝐧𝐲𝐭𝐢𝐦𝐞 - 𝐁𝐢𝐠𝐠𝐞𝐬𝐭 𝐕𝐨𝐥𝐮𝐦𝐞 𝐆𝐚𝐢𝐧𝐞𝐫𝐬 24𝐡 $BEAMX $CARV $AKT
𝐓𝐡𝐞𝐬𝐞 𝐂𝐨𝐢𝐧𝐬 𝐂𝐚𝐧 𝐏𝐮𝐦𝐩 𝐀𝐧𝐲𝐭𝐢𝐦𝐞 - 𝐁𝐢𝐠𝐠𝐞𝐬𝐭 𝐕𝐨𝐥𝐮𝐦𝐞 𝐆𝐚𝐢𝐧𝐞𝐫𝐬 24𝐡 $BEAMX $CARV $AKT
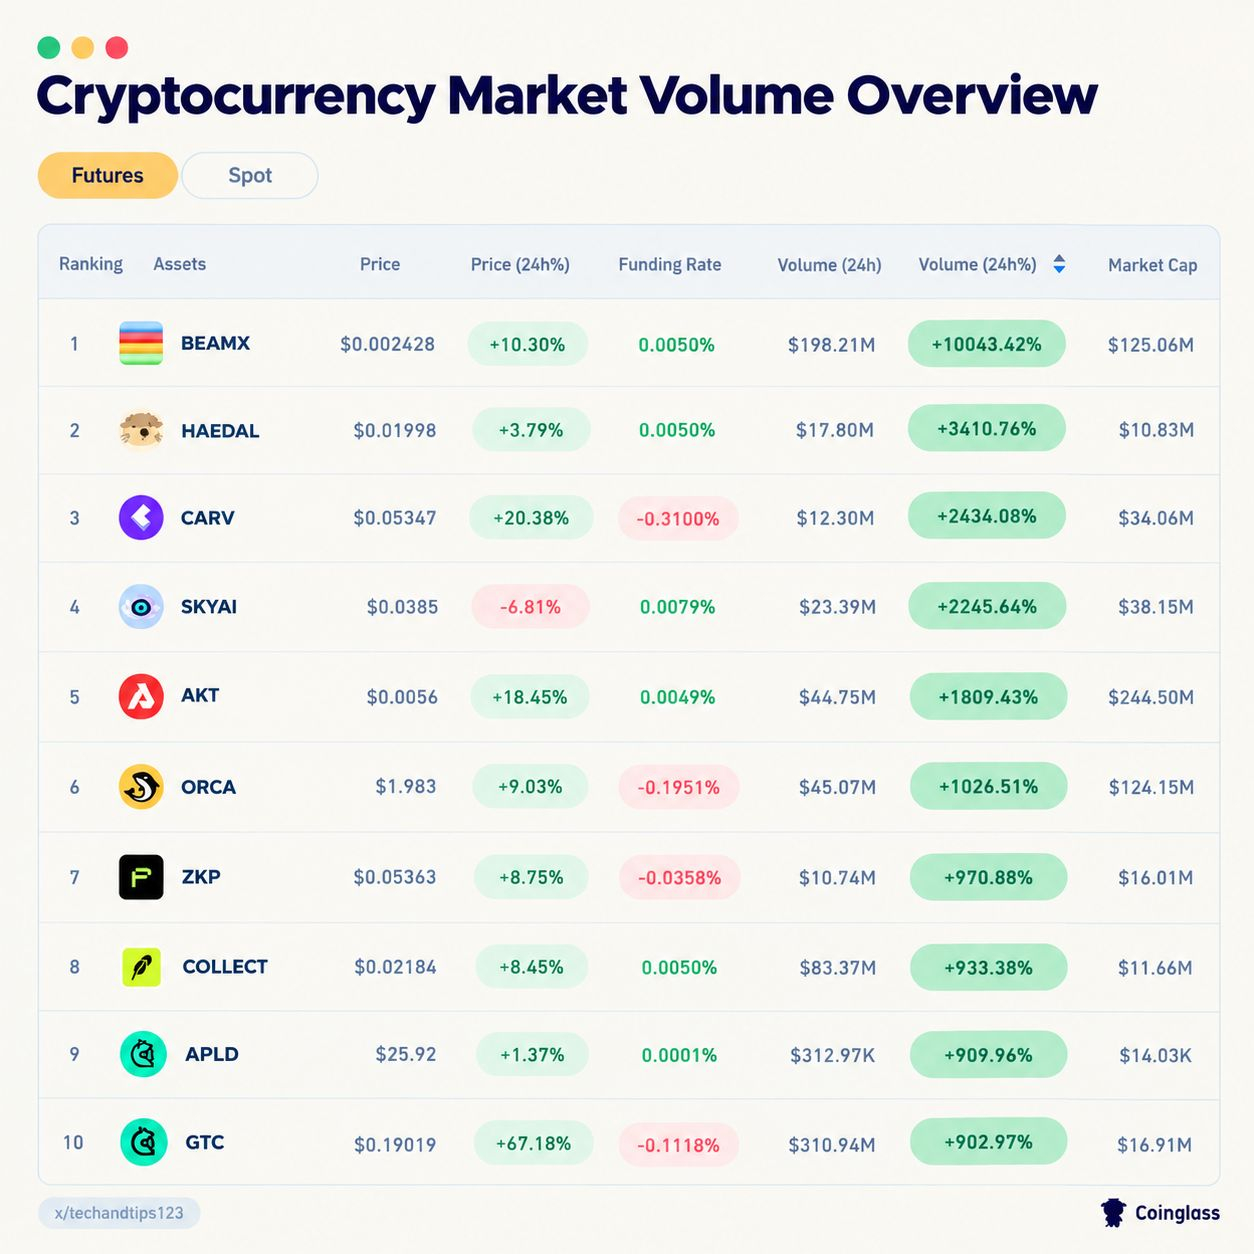
1
640
Connectez-vous pour découvrir plus de contenu
Rejoignez la communauté mondiale des adeptes de cryptomonnaies sur Binance Square
⚡️ Suviez les dernières informations importantes sur les cryptomonnaies.
💬 Jugé digne de confiance par la plus grande plateforme d’échange de cryptomonnaies au monde.
👍 Découvrez les connaissances que partagent les créateurs vérifiés.
Adresse e-mail/Nº de téléphone
Sujets d’actualité
BinanceLaunchesBinanceIntelligence
774,115 vues
4,858 mentions
#binancelaunchesbinanceintelligence 🚨 WHAT IF THE NEXT BIG EXCHANGE BATTLE ISN’T ABOUT FEES? 👀
Binance just made a bigger move than adding another AI chatbot.
With Binance Intelligence, AI is moving deeper into the exchange — from understanding market data to building trading workflows. 🤖⚡
The real question is:
Who has the best liquidity?
Or who has the smartest AI layer?
If users can research, test ideas and manage trading workflows without switching between different tools, the exchange itself could become a financial assistant.
That could be a much bigger shift than it looks today.
If Binance Intelligence drives more users, more strategies and more trading activity, $BNB could become one of the tokens to watch. 👀
Is Binance building the future of AI-powered finance?
$BNB
#binancelaunchesbinanceintelligence #BinanceAI #CryptoAI #AITrading
Suleman Khan Haqqani
·35 mentions J’aime
·32k vues
BTCFallsBelow$84K
39,492 vues
133 mentions
DubaiVARAIssuesReserveAssetAuditCircular
13,309 vues
480 mentions